Adding AI to Your SaaS Without Blowing It Up
How to add AI features to an existing SaaS without wrecking UX or your margins: where to start, which models to pick, how to control API costs, and patterns users actually adopt.
Quick verdict for founders Most existing SaaS products get the first real win from a narrow AI feature on top of customer data: search, summarise, draft, explain, or extract, not a generic chatbot over everything. Start with a low-stakes, user-in-the-loop workflow, pick a mainstream LLM API, and design around cost per user from day one. If you haven’t done the basic maths on AI unit economics yet, it’s worth pairing this with a budget-level view of what an AI MVP really costs to run in production. Best for Existing B2B SaaS teams adding their first or second AI feature Avoid if You have not validated the underlying user pain; AI will not fix a broken core product Starting point AI-assisted search, summarisation, drafting, or extraction on your own data Main strength Concrete guidance on model choice, cost maths, UX patterns, and adoption Main risk Runaway API costs and low adoption if you skip instrumentation and UX discipline Start with the problem, not the model Audit workflows before you touch an API AI does not magically rescue weak products. Industry playbooks emphasise validating that AI is needed at all; many issues are better solved with rules, templates, or cleaner UX. Before choosing a model: Pull usage analytics: funnels, time-on-task, error rates, rage clicks. Read support tickets and NPS comments for recurring friction. List workflows that are slow, repetitive, or error-prone inside your app: support replies, report writing, onboarding, configuration, data entry. Confirm AI is actually required People + AI research from Google explicitly recommends checking whether deterministic logic or UX fixes are enough before adding ML. Run through each candidate workflow and ask: Is the task fuzzy / language-heavy (summarise, interpret, draft, classify)? AI is more likely to help. Could a simple rules engine, better defaults, or canned templates eliminate 80% of the pain? Is the required behaviour predictable and auditable (e.g. compliance checks), where AI’s stochastic output may be a liability? Choose low-stakes, user-in-the-loop use cases first Guides on adding AI to SaaS consistently recommend low-stakes, user-in-the-loop workflows as the first implementation: summarisation, drafting, extraction, or search on existing user data. These boost productivity but keep a human in control when the model is wrong. Examples that tend to work as first features: AI search across tickets, docs, or transactions with answer snippets grounded in your own data. Summarise long objects: support threads, CRM timelines, deal notes, logs. Draft and rewrite : email replies, product descriptions, report sections. Extract fields from unstructured text: invoices, KYC docs, contracts. Explain complex outputs in plain language: pricing models, analytics, risk scores. Tie AI features to hard metrics, not vanity SaaS AI playbooks warn against treating “AI usage” as a north-star metric; the best-adopted features map to existing business metrics such as activation, retention, expansion, or support deflection. For each candidate feature, define a specific target: Onboarding copilot → faster time-to-first-value, higher activation rate. Support suggested replies → lower median response time, higher ticket deflection. AI report drafting → reduced time-on-task for report creation, more reports sent per account. Decide early where AI lives in your product Where AI sits in your information architecture shapes adoption: Core workflow (e.g. “Summarise call” button in call logs) – high-visibility, but must be robust. Sidekick (copilot panel) – good for multi-surface assistance without hijacking flows. Pro add-on – advanced automation reserved for higher tiers or specific user types. Research on AI adoption in software tools finds that features integrated into existing workflows and tooling see higher usage than separate tools requiring behaviour change. Choosing models: OpenAI, Claude, Gemini, and open source Define constraints before comparing models Model selection should follow your constraints, not marketing hype: OpenAI's guidance for picking a model: Sol for hard reasoning, Terra to balance cost, Luna for high volume Gemini splits a free developer tier from paid, where content is not used to improve Google's products Latency : what’s acceptable per interaction (e.g. <1s inline, <5s for larger summaries)? Cost per user per month : what can you spend at your current ARPU? Data residency and compliance : EU, GCC, or sector-specific (finance, healthcare) constraints. Error tolerance : can users easily correct outputs, or does a mistake have financial/compliance impact? Mainstream provider options Many modern SaaS teams can ship useful AI features without an in-house data science team because high-level APIs from providers such as OpenAI, Anthropic Claude, and Google Gemini cover most common language use cases. If you are still deciding between ChatGPT, Claude, and Gemini as your primary operator console, it helps to benchmark them against each other in real founder workflows rather than toy prompts. OpenAI GPT‑5.6 Sol : the flagship, for complex reasoning and coding. Listed at $5.00 per 1M input tokens and $30.00 per 1M output tokens on short context. GPT‑5.6 Terra : the balance of intelligence and cost, at $2.00 input and $12.00 output per 1M tokens — the sensible default for most SaaS features. GPT‑5.6 Luna : cost-optimised for high-volume workloads, at $0.20 input and $1.20 output per 1M tokens. Cached input and batch tiers cut this further, so model the cached rate for anything with a repeated system prompt. Prices move, and long-context requests bill at higher rates than the short-context figures above, so read them off OpenAI's live pricing page during cost modelling rather than hard-coding them. Anthropic Claude Claude model families (such as Opus, Sonnet, Haiku) are priced per million tokens for input, output, and cache; list sheets also describe discounted batch tiers for offline processing. Google Gemini Gemini APIs distinguish between multiple model families (for example, Gemini 2.5 Pro and Flash, and newer 3.x Flash / Flash-Lite variants), with substantial price and performance differences that affect suitability for high-volume SaaS features. Always consult the current Gemini API pricing and model-lineup docs before locking in a choice, as Google has been deprecating and replacing specific 2.x models over time. Comparisons based on vendors’ own list prices show that the same workload can vary by one to two orders of magnitude in cost depending on provider and model, so aligning model choice with workload economics is critical. If you want a more opinionated, founder-first comparison of Gemini vs ChatGPT, focus on the trade-offs that matter for real ops work: context length, reliability, and pricing quirks. When to use premium vs cheaper models A practical split: Premium models (e.g. GPT‑5.6 Sol, Claude Opus 5): Complex, multi-step reasoning, planning, and agents. High-value actions where better accuracy clearly pays for itself. Low-volume features (e.g. weekly strategic report generation). Cheaper / “flash” or small models (e.g. Gemini 3.x Flash and Flash‑Lite, Claude Haiku 4.5, GPT‑5.6 Luna, or open source): High-volume operations like classification, tagging, extraction. Inline rewrite / summarise buttons used tens or hundreds of times per user per day. Background tasks: nightly enrichment, batch document processing. Where managed open-source models fit Managed open-source LLM hosting (across various vendors) can make sense when: Your workload is predictable and high-volume, making per-token savings meaningful. You have strict data-control or residency requirements that are easier to satisfy on your own cloud or a regional provider. You are comfortable handling more of the reliability and scaling trade-offs yourself. Design a provider-agnostic interface Model churn is a constant. To avoid rewrites: Define an internal AI client interface (e.g. generateText() , classify() , extract() ) in your backend. Map each method to concrete providers via adapters (OpenAI, Anthropic, Gemini, open source). Centralise prompts and model configuration so that swapping a model or version is a configuration change, not a code change. Many teams test multiple models against the same anonymised workload traces before committing, using this abstraction to switch providers without touching feature code. API cost modelling for SaaS Turn per-million token prices into per-user costs Token pricing only makes sense once translated into per-feature and per-user unit costs. A simple flow: The per-million-token rates to build a cost model on, with separate short and long context columns Anthropic's API tab prices Opus, Sonnet and Haiku per million tokens, with prompt caching billed separately Map a typical session : for a feature, estimate how many AI calls are made in a normal session and what each call looks like. Estimate tokens per call: approximate input size (prompt + user data) and output size. Apply pricing : multiply total input and output tokens by the provider’s per-million token prices to get a per-session cost. Scale to monthly per-user : multiply by expected sessions per user per month and compare against plan pricing and gross margin. This is also the point where you sanity-check your AI feature roadmap against your pricing model: are you going to bundle, meter, or upsell? If your ARPU is modest, you may need to be as disciplined about AI tokens as you are about infra, the same way you would when you model the real cost of an AI MVP for investors or co-founders. Work explicit token budgets into the UX Cost and UX are coupled. Define: Maximum input sizes : cap characters or tokens per request (e.g. max length per note to summarise). Response size limits : encourage concise outputs (e.g. “50-word summary”) and truncate where acceptable. Number of steps : minimise unnecessary intermediate calls in multi-step flows. Model typical, power, and abuse scenarios Token usage distributions are skewed. Guides on AI cost management suggest modelling: Average user : core assumption for bundling into plans. Power user : heavy but reasonable use; informs whether you need an add-on tier. Abusive/automated use : scripts hitting endpoints or misconfigured integrations; informs caps and rate limits. There are public anecdotes of developers incurring unexpectedly large Gemini API bills due to misconfigured keys or usage controls; regardless of provider, this risk underlines the need for strict key security, rate limiting, and spend monitoring for AI features. Match models to interactive vs background work To keep costs and latency under control: Use cheaper or batch endpoints for non-interactive jobs: nightly enrichment, bulk analysis, backfills. Reserve premium models for user-facing interactions where extra accuracy and reliability clearly improve business outcomes. Pricing strategy for AI features Research on SaaS packaging suggests calculating marginal cost per active AI user (and variance) before deciding how to charge. A pragmatic approach: Light usage features (occasional summaries, simple suggestions): often bundled into existing tiers as table stakes. Heavy usage features (batch processing, agents, bulk document analysis): offered as add-ons or higher tiers with explicit usage allowances. Metering : for very heavy users, expose usage-based billing above an included allowance. Communicate what is included, what is metered, and what happens at limits; guidance for AI pricing stresses clear communication and readiness to adjust packaging as you learn. The same discipline you’d use when assessing the real cost of tools like ChatGPT, Claude, Cursor or Lovable in your own stack should apply to how you expose AI value and limits to your customers. Guardrails against runaway spend To avoid bill shocks: Set per-tenant and per-key rate limits at the gateway. Add hard quotas per plan tier (e.g. monthly AI tokens or tasks) with soft warnings as users approach them. Implement spend alerts and kill switches at the provider and your own monitoring layer. Security, reliability, and compliance for AI APIs Treat AI keys as high-sensitivity secrets Public incident reports and provider guidance make it clear that misconfigured or exposed API keys can lead to large unintended bills and abuse. Store provider keys in secure secret managers. Rotate keys regularly and scope them per environment or per-project where possible. Never expose keys to browsers or mobile apps; route all calls through your backend. Add request-level safety and validation Input validation : ensure user inputs meet size and type constraints before hitting the model. Prompt sanitisation : strip or escape system prompts if users can edit prompt-like text. Output filtering : run generated text through content filters for PII or policy-violating material when needed. Plan for outages and degradation AI APIs have rate limits and occasional incidents. To avoid breaking core workflows: Implement circuit breakers around AI calls; fail fast instead of queuing unbounded work. Define fallback behaviours : e.g. simple keyword search when semantic search is down, or manual flows when drafting fails. Use retries with backoff for transient errors, and surface graceful messages to users. Data handling, audits, and vendor policies For B2B and especially regulated industries: Document what is logged, what is sent to vendors, and retention periods. Review each provider’s data use, retention, and training policies and reflect these in privacy docs and contracts. Offer configuration where feasible: toggles for sending specific data fields to third-party AI or keeping them local. Set up monitoring on AI spend, latency, and error rates to catch issues early. UX patterns that work for AI in SaaS Use established interaction patterns UX research on AI features stresses that interaction patterns matter more for adoption than the specific model. Common patterns include: Inline assist : contextual buttons (often a “magic wand”) beside fields or editors to draft, rewrite, or explain current content. Side-panel copilot : a docked assistant that can see the current page and offer suggestions or actions. AI-powered search : search boxes that retrieve and summarise relevant documents from your own data with citations and filters. Task wizards : multi-step flows where AI handles specific steps (e.g. generating copy) but users can review and edit before applying. Inline vs sidekick: when to use which Inline actions work best when the user has a clear, focused task (write email, fill form) and AI can speed that task up without context-switching. Side-panel copilots suit exploratory or multi-step work: planning projects, diagnosing issues, exploring complex data. Many sources note that generic full-screen AI chatbots are often over-built relative to adoption; task-specific embedded AI sees better engagement. That’s the same pattern you can observe in tools like Notion AI and modern coding assistants: the most-used capabilities are usually the ones that sit directly inside existing workflows rather than separate “AI labs” screens. System-initiated prompts, not AI everywhere UX case studies highlight an anti-pattern: “AI everywhere without context” — surfacing AI aggressively in too many places without clear intent or explanation. Instead: Use subtle, context-aware prompts like “Summarise this conversation?” next to long threads. Trigger AI suggestions when the user has clearly completed a step (e.g. finished writing a draft). Avoid blocking users behind AI; manual controls should always be available. Scaffolding for trust and error handling AI product design guidance stresses transparency, user control, and clear error handling to maintain trust. Practical patterns: Show sources and citations for AI answers based on your data. Explain in plain language what the AI can and cannot do on the onboarding screen. Offer quick ways to edit, regenerate, or give feedback on outputs. Display fallback messaging when the AI is unavailable, not just generic errors. Studies on adoption report that explicit onboarding, explainability, and feedback loops materially improve uptake relative to simply adding new buttons. Accessibility and localisation, especially for MENA MENA and Arabic use cases introduce additional constraints: Evaluate models on Arabic and RTL performance specifically; not all English-strong models perform as well in Arabic content or interfaces. Design for RTL layouts where appropriate, and test prompts and outputs in Arabic and bilingual scenarios. If serving GCC/UAE, consider data residency requirements; this may steer you towards specific clouds or managed open-source models. If your roadmap includes Arabic-first or GCC-focused products, it’s worth treating RTL and localisation as first-class concerns during your AI feature design, not an afterthought you patch once you start landing regional enterprise deals. Shipping AI features users actually adopt Start from analytics and real friction Playbooks for adding AI to SaaS repeatedly warn against “AI for the sake of AI”; they recommend targeting validated pain points backed by metrics and user feedback. A practical loop: Use product analytics to find flows with high time-on-task, error rates, or drop-offs. Map these to jobs-to-be-done and hypothesise how AI can compress them. Validate with interviews or design prototypes before engineering. Co-design with power users, then A/B test Before deep integration: Prototype AI flows in design tools or low-code builders. Co-design with a small group of power users who feel the pain most. Once implemented, A/B test AI-assisted vs non-AI flows on completion time, success rates, and support tickets. White-papers on SaaS adoption show higher feature utilisation when new capabilities are tied to clear outcomes and reinforced through in-app prompts and training, which applies directly to AI features. Measure adoption by feature, not “AI overall” Instrument per-feature usage : AI search, AI drafting, AI summarisation, etc. Correlate usage with business outcomes : activation, retention, expansion, support tickets. Be ready to kill or rework AI features that don’t move core metrics. Case studies report that AI features that compress existing workflows with clear ROI (for example, reducing repetitive documentation or support work) see higher adoption than features demanding new behaviours. The same principle is behind why focused "agents" for support or ops often outperform generic assistant chatbots in real SaaS environments.
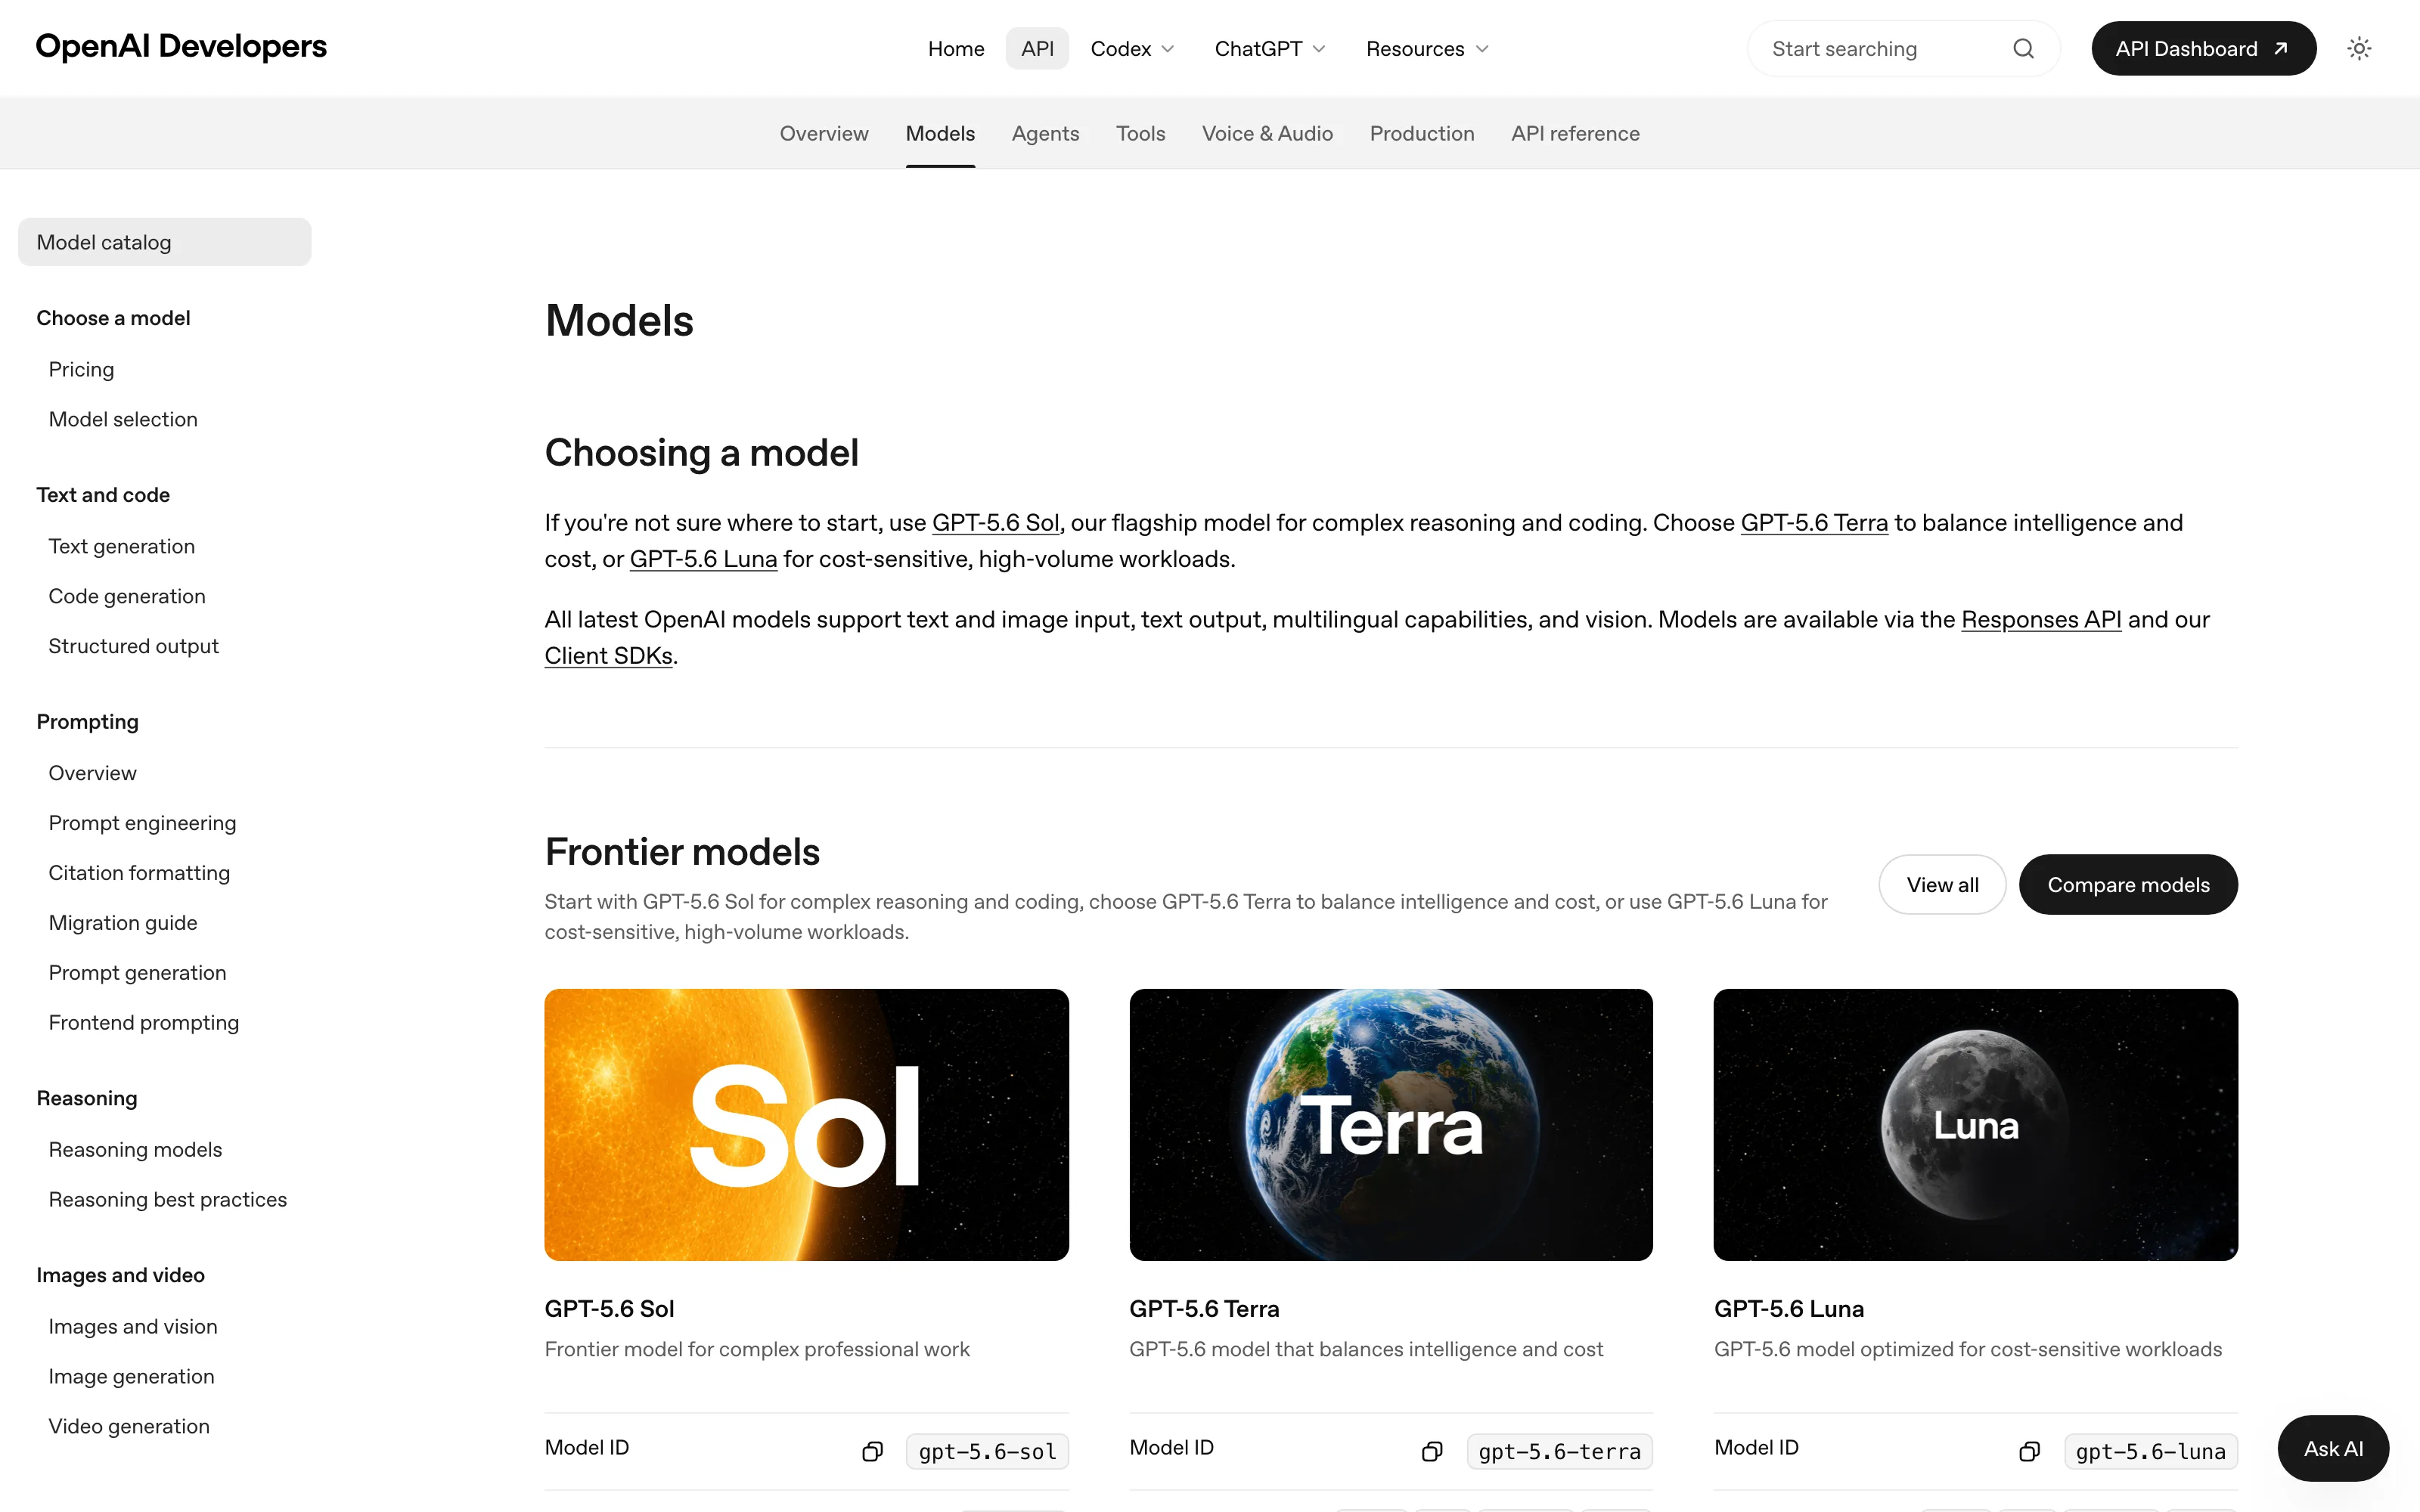 OpenAI's guidance for picking a model: Sol for hard reasoning, Terra to balance cost, Luna for high volume
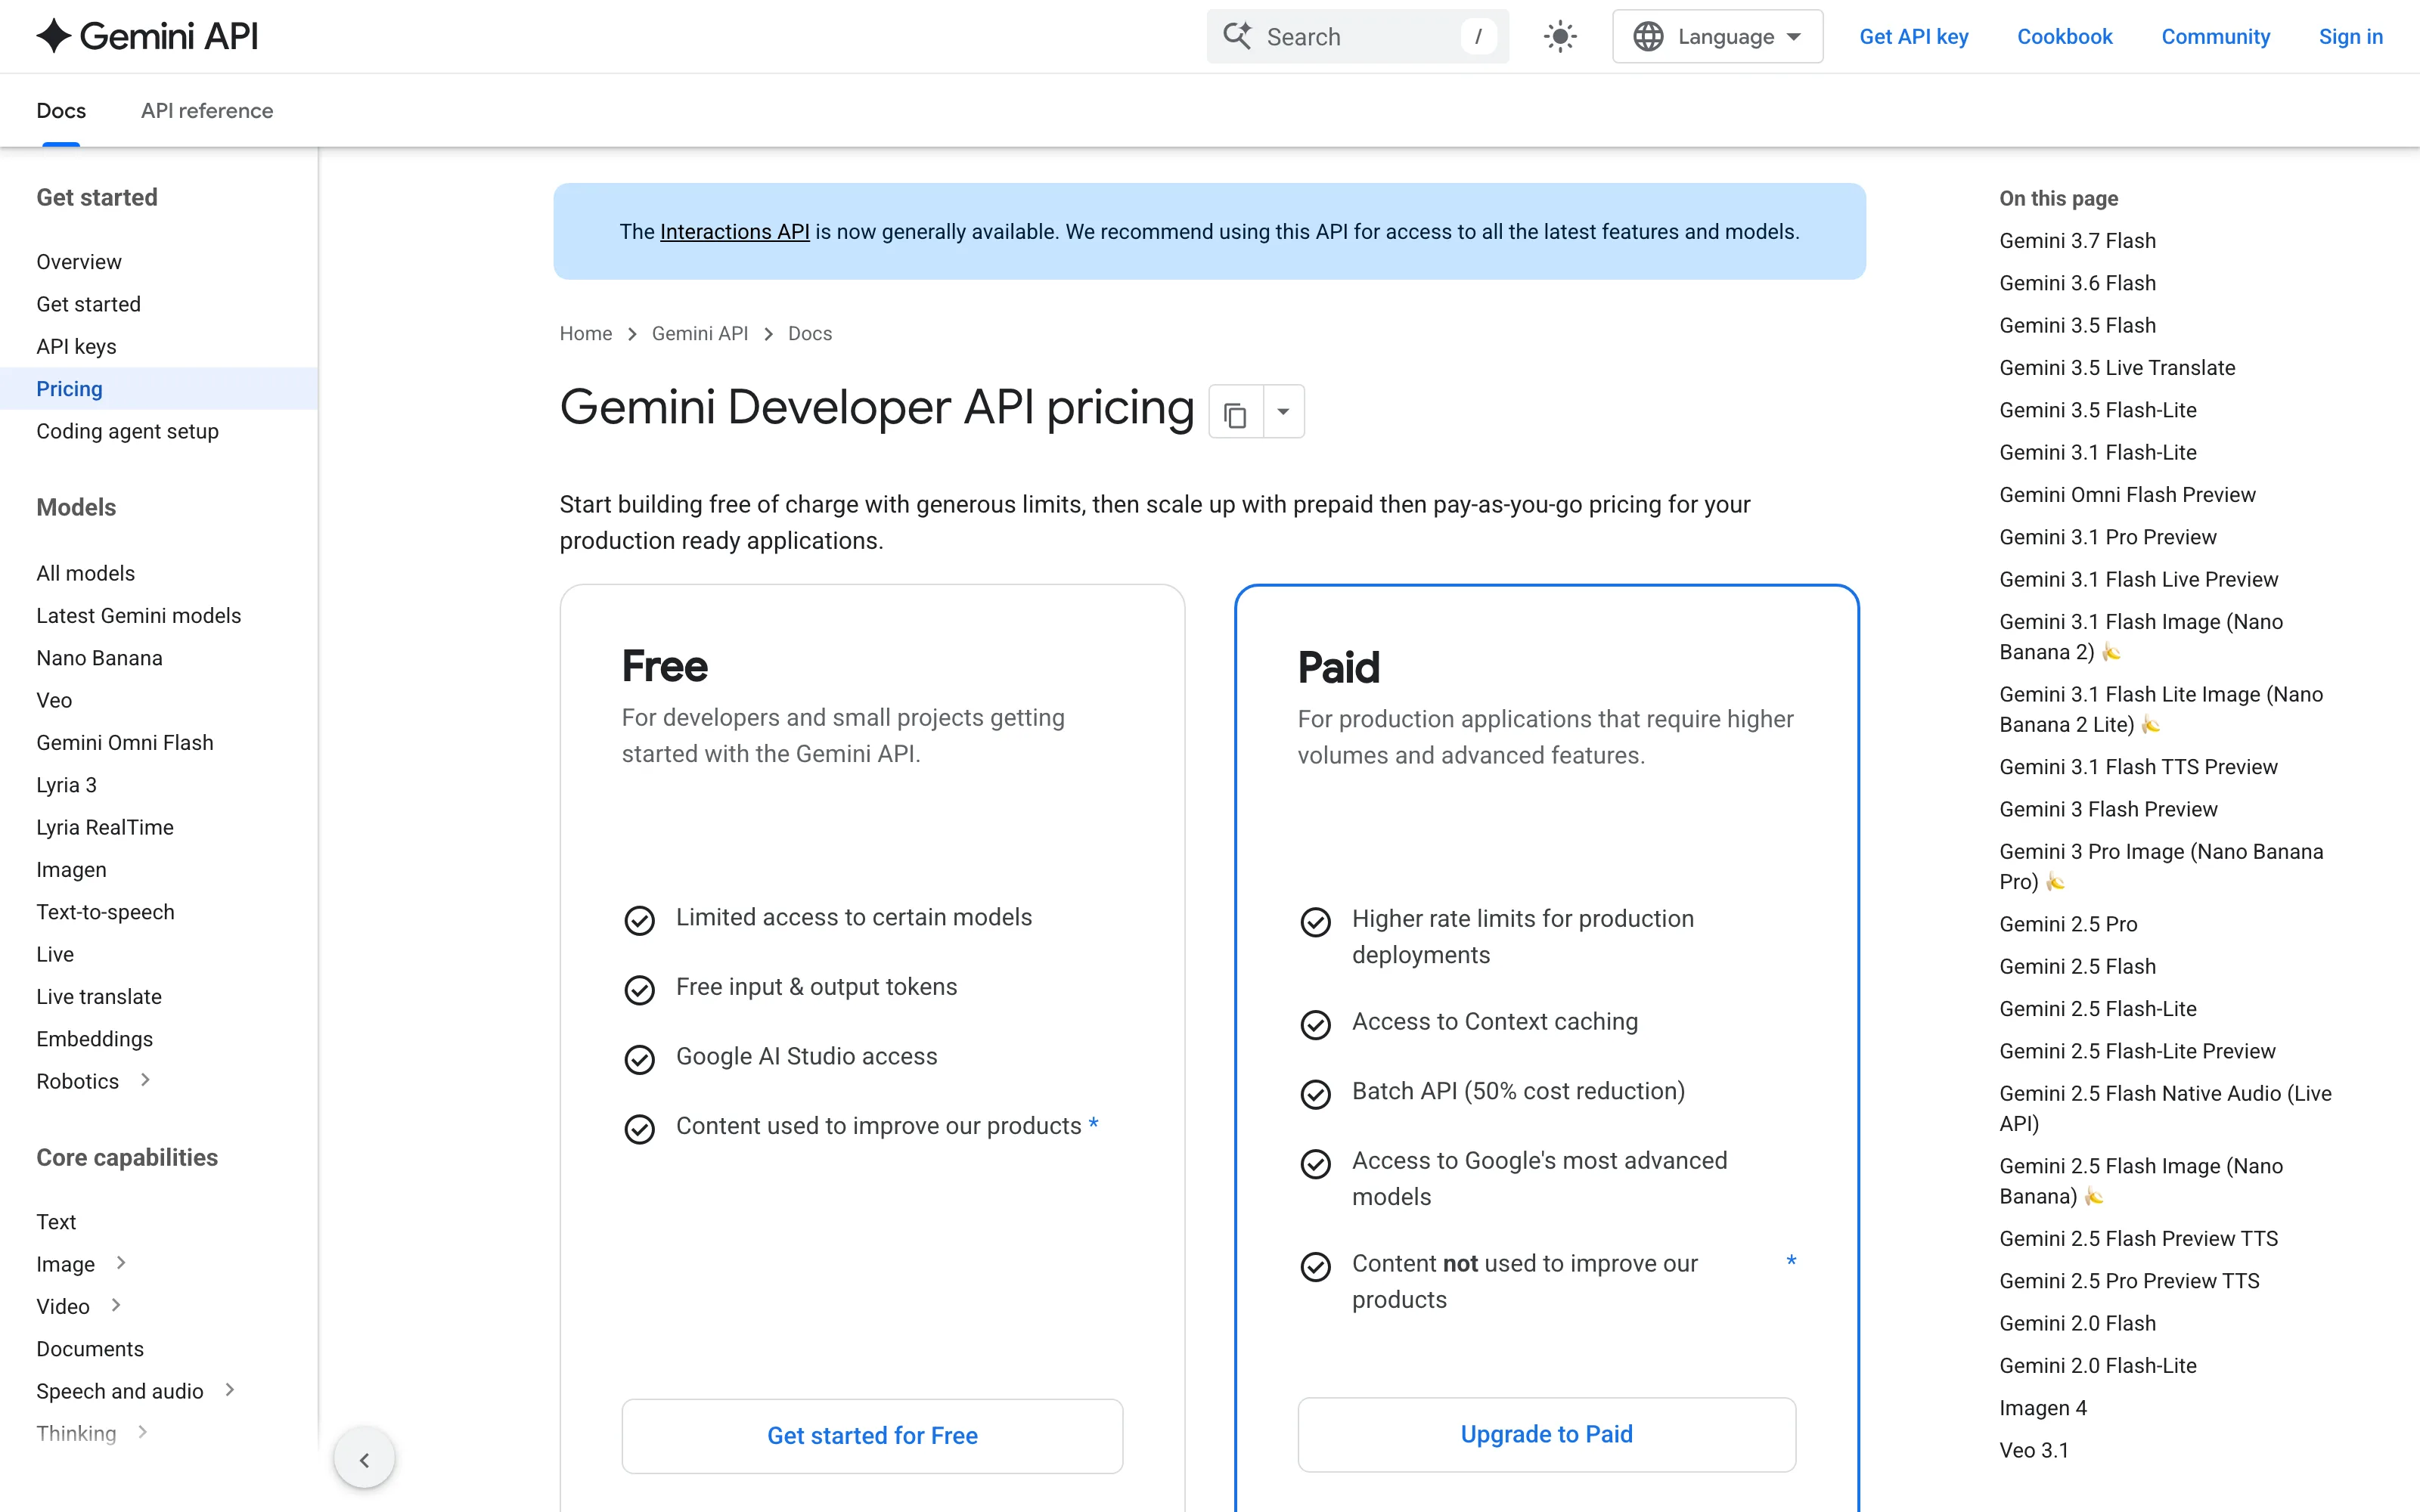 Gemini splits a free developer tier from paid, where content is not used to improve Google's products
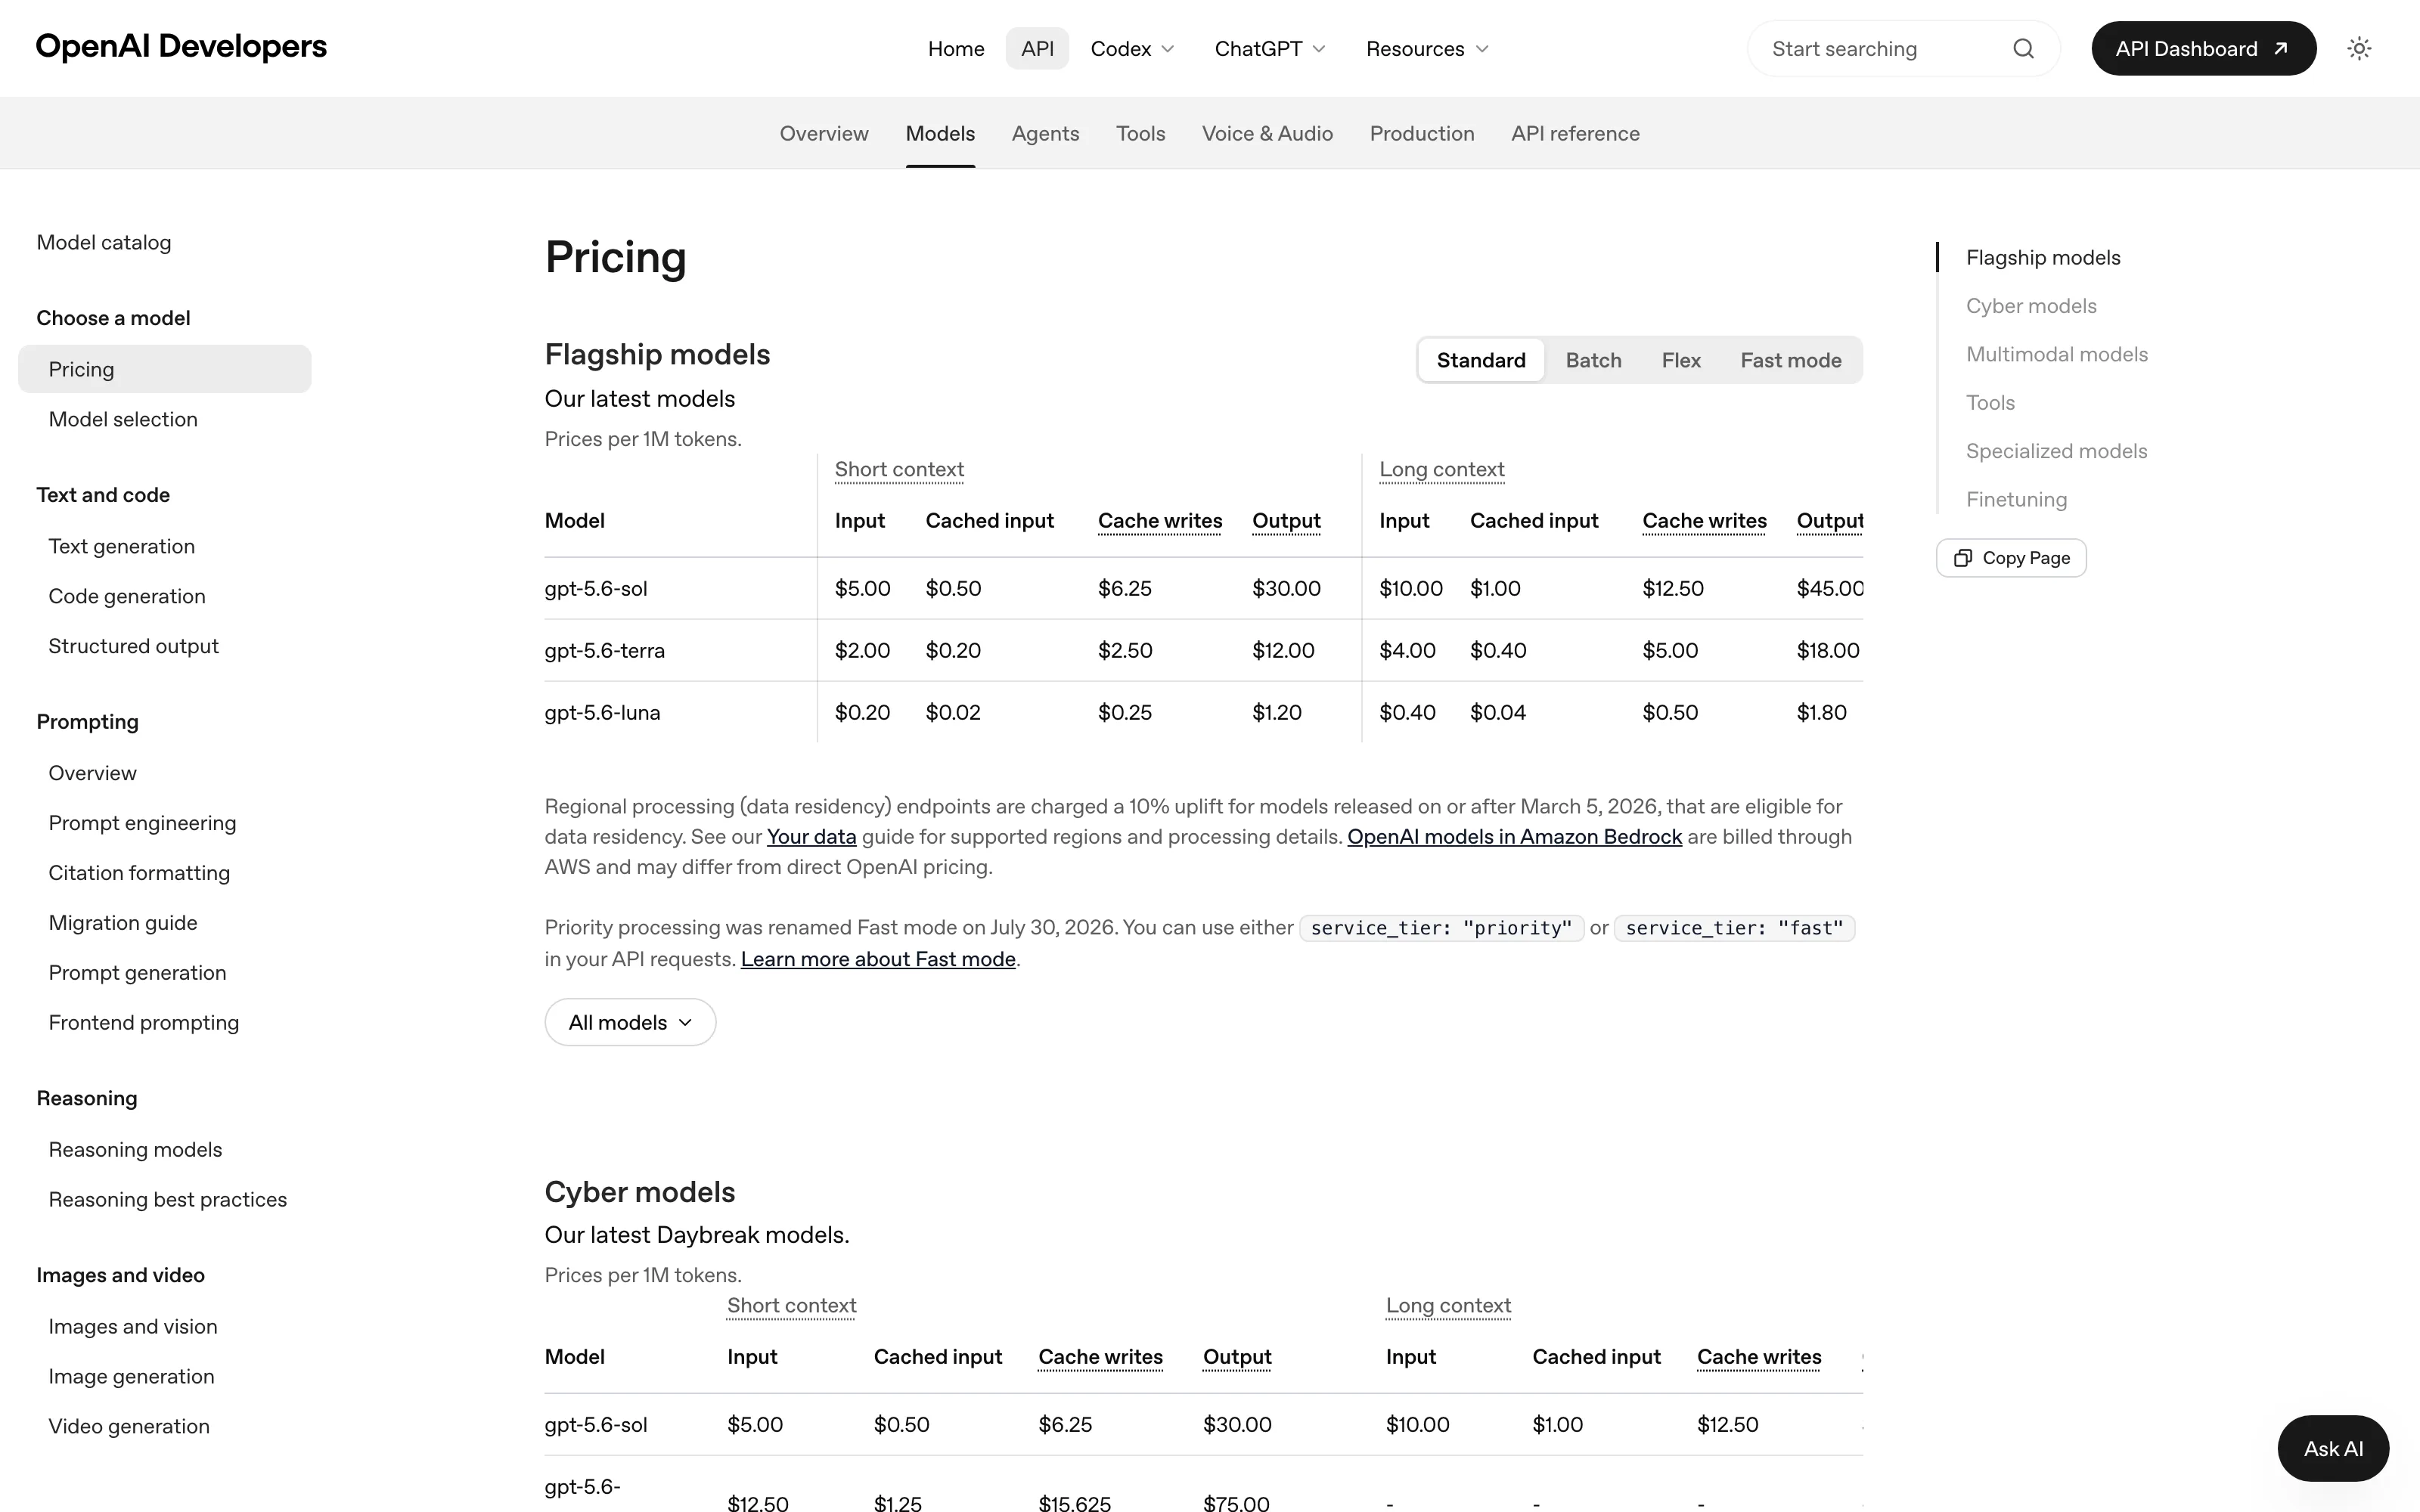 The per-million-token rates to build a cost model on, with separate short and long context columns
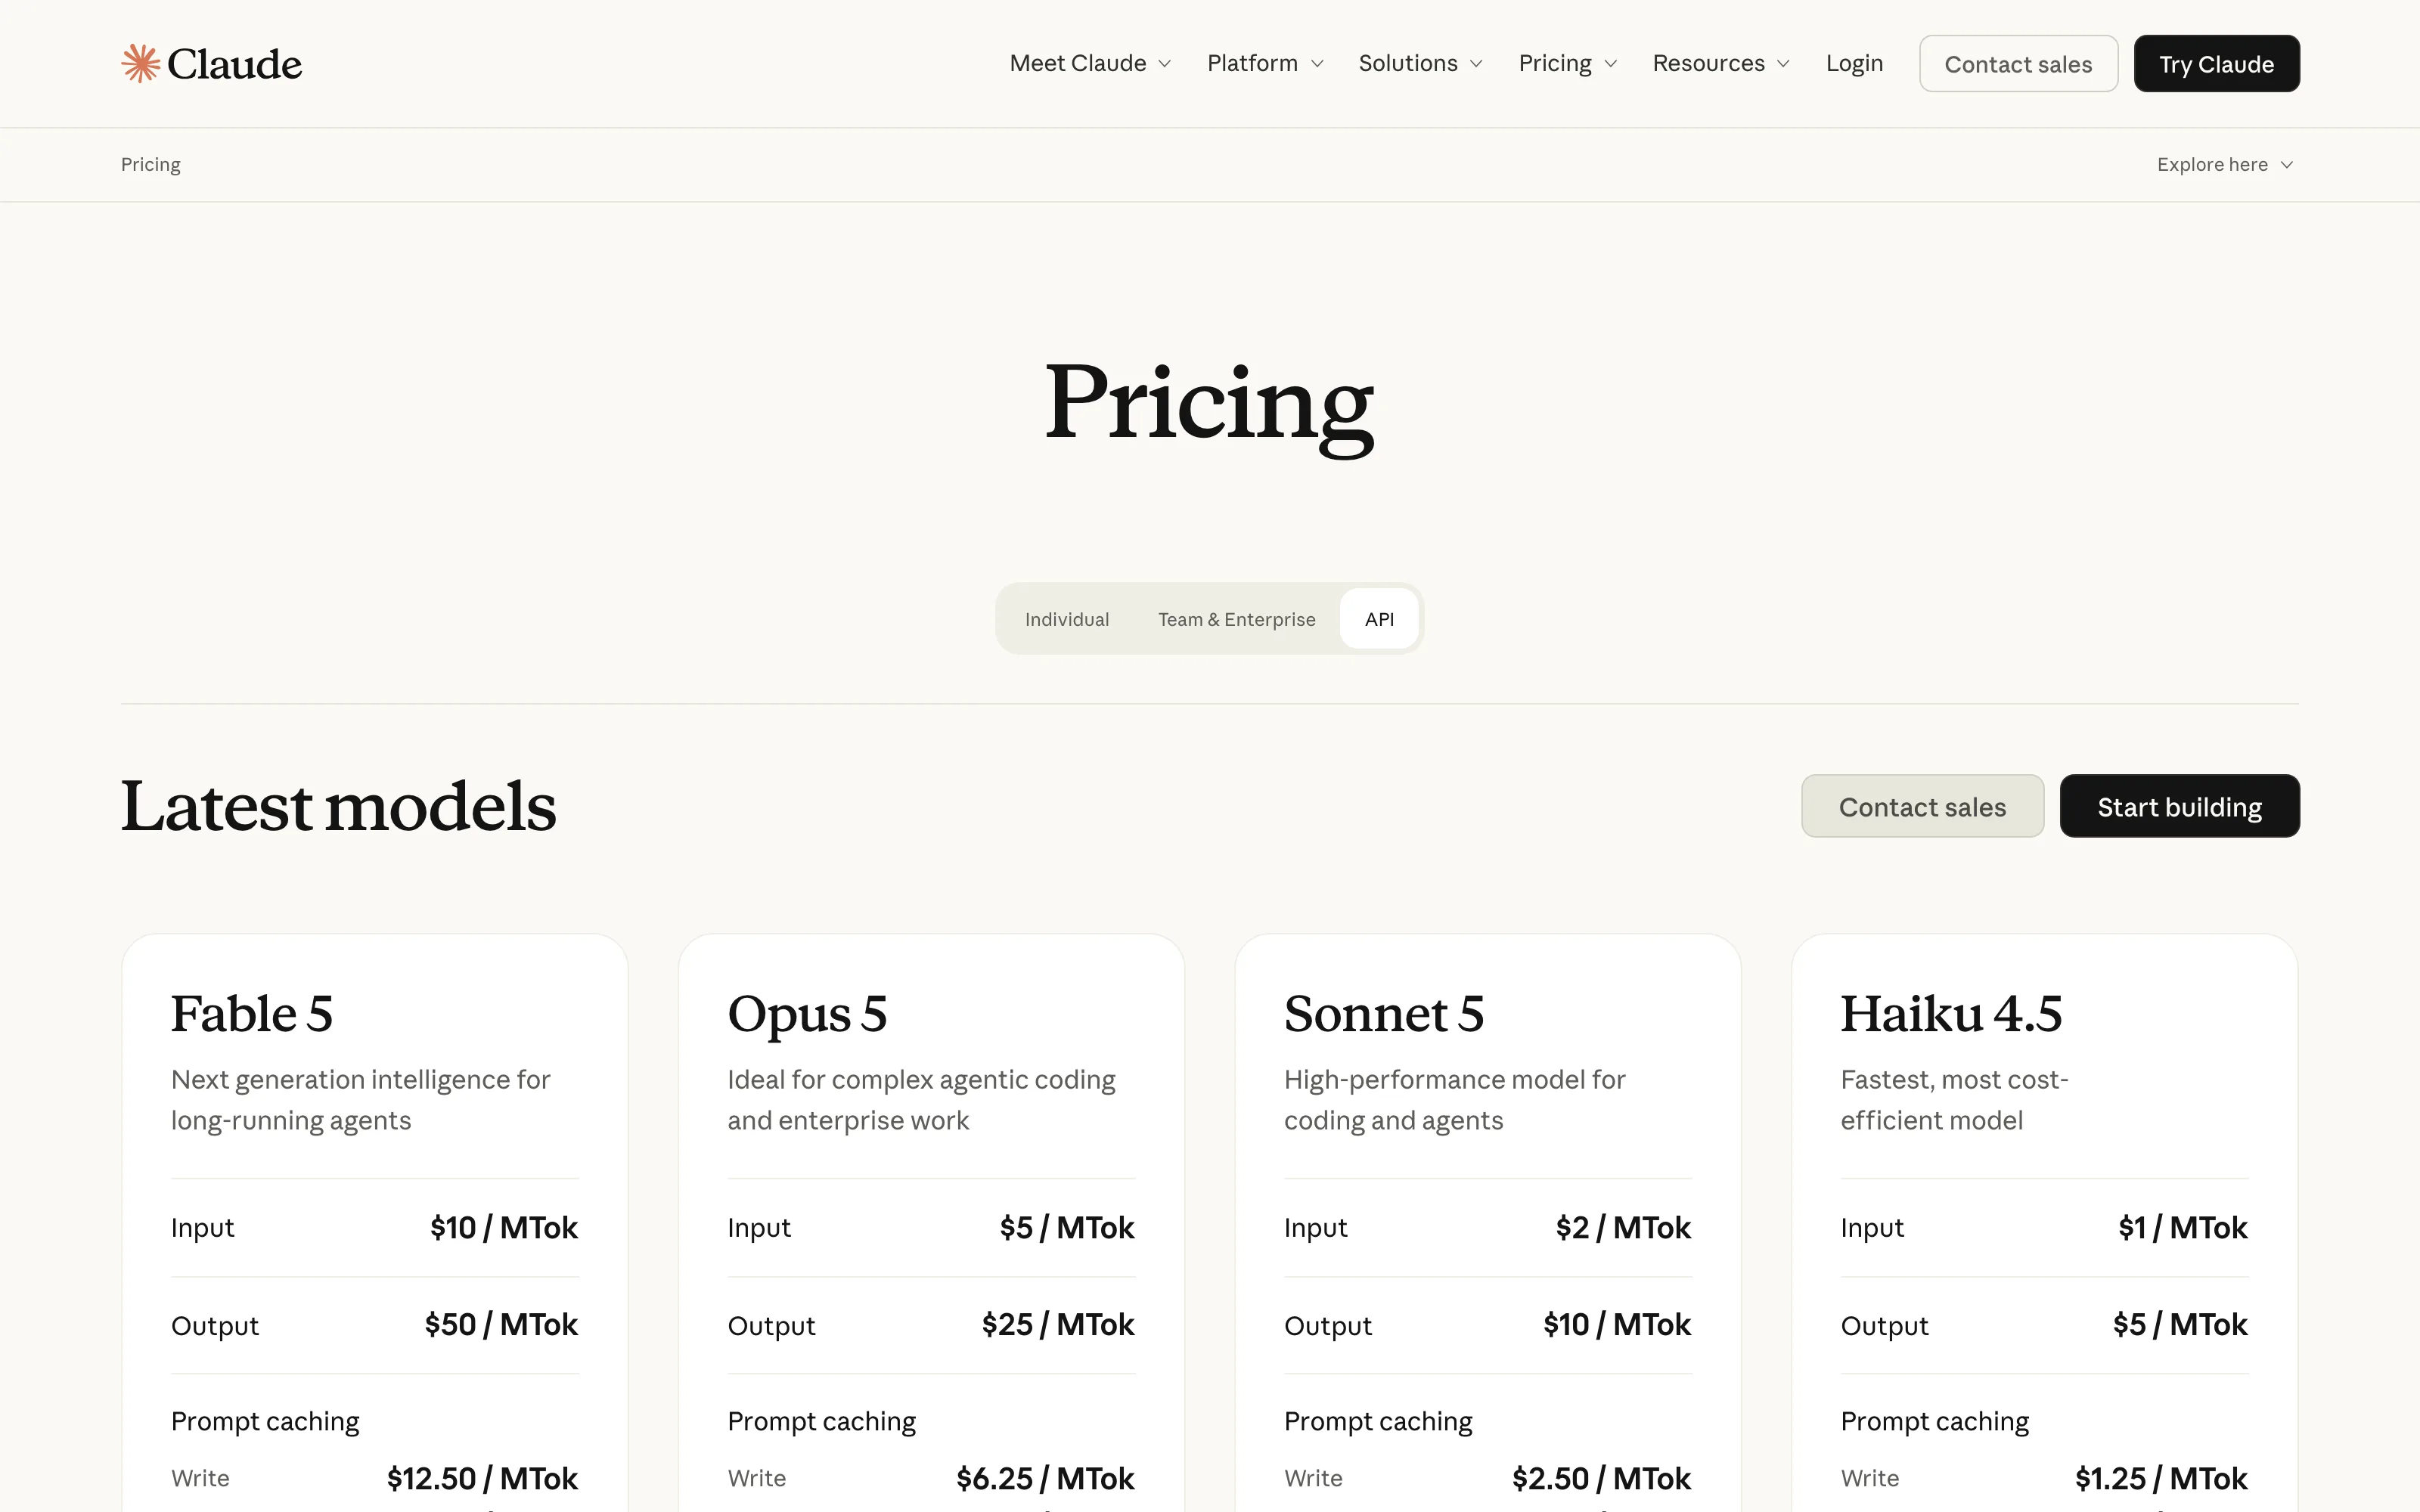 Anthropic's API tab prices Opus, Sonnet and Haiku per million tokens, with prompt caching billed separately
Browse the site
Home
about
story
work
expertise
ai
ai ai product development
ai ai agents
ai ai automation
ai ai consulting
ai arabic ai products
ai kuwait
toolkit web
toolkit claude
toolkit lovable
toolkit notion
toolkit webflow
toolkit shopify
toolkit wordpress
toolkit ai solutions
services
services business strategy
services growth planning
tools
blog
listening
books
stack
contact
quote
privacy
terms