Manus AI Review 2026: Autonomous Agent Reality for Founders
A grounded 2026 Manus AI review: what its autonomous agents can genuinely execute for founders, where they break, and how its hybrid subscription + credit model really behaves in practice.
Quick verdict: powerful agent, risky as core infra Manus is a strong general-purpose autonomous agent for research, drafting, light coding, and small data workflows. It runs tasks in a cloud sandbox, can browse, code, analyse data, and design slides or simple web apps from a single prompt AI IdeList Awesome Agents . For founders and operators, it behaves more like a flexible junior analyst and prototyper than a reliable engineer or production automation platform. Its biggest upside is speed on messy, open-ended work like market research, synthesis, and first-draft content. If you mainly need a research copilot, you should also compare it against focused tools like Perplexity ( Perplexity review 2026 ), or more general assistants like ChatGPT and Claude ( ChatGPT vs Claude for startup work ), which can be cheaper and more predictable for day-to-day queries. Its biggest downside is cost opacity: subscription plus credits, difficult-to-predict burn, and user reports of unexpectedly high monthly bills, including examples in the tens of thousands of dollars Future Stack Reviews Reddit . If you’ve already been burned by surprise infrastructure bills (for example on hosting or AI tools), it’s worth reading how to cap spend and monitor usage ( deploying side projects on Vercel safely ) and applying the same discipline here. Best for: founders and teams who want autonomous research, drafting, and small utilities, with tight spend limits. Avoid if: you need deterministic behaviour, strict SLAs, or predictable unit economics per task. Starting price: Manus uses a subscription plus credits model. As of August 13, 2026, the Help Center shows paid tiers starting from US$20/month (with a discount for annual billing), each including a monthly credit allowance — 4,000 credits on the $20 tier — rather than billing credits separately; other tiers and local prices may vary and are subject to change. Manus Help Center . Main strength: genuinely autonomous multi-step execution for research and synthesis, including parallel web work Botonomy AI . Main limitation: opaque, spiky credit consumption and weak reliability for complex software projects or regulated workflows. Positioning Manus in 2026: what it claims to be From chat assistant to autonomous agent platform Manus is positioned as a general-purpose autonomous AI agent: a user gives it a high-level goal in natural language and it plans and executes multi-step work in an isolated cloud sandbox rather than just replying in chat Awesome Agents . That sandbox comes with its own browser and tooling, so the agent can: Manus presents itself as a general agent that executes tasks rather than just replying Open and explore web pages Write and run code Analyse datasets Design slides and visual assets Build and deploy simple web apps Future Stack Reviews Multiple independent reviews describe Manus as a cloud-based general-purpose autonomous agent focused on executing multi-step tasks rather than chat completions. Meta announced an acquisition of Manus valued at more than US$2 billion in late 2025, but by mid‑2026 Chinese regulators had ordered the deal to be unwound and reports described Meta cutting Manus off from its internal systems and beginning to sunset the integration; Manus continues to operate as a separate agent platform while that process plays out Vellum AI Sacra . The positioning is “agent-as-platform” with SDK access so other tools can build on top of its orchestration Sacra . If you’re evaluating Manus alongside other agentic coding or automation stacks, you’ll likely also be looking at tools like Claude Code or Cursor ( best AI coding tools 2026 ), which take a different stance on control and observability. Architecture at a high level Public write-ups describe a central planner coordinating specialised tools and sub-agents inside that sandbox AI IdeList . In practice, this means: The planner breaks a goal (“Analyse competitors and draft a deck”) into sub-tasks. Sub-tasks call tools: a browser, code runner, data analyser, slide designer, web-app builder Future Stack Reviews . The agent iterates until it decides the goal is met or it hits internal limits. This is closer to an orchestrated workflow engine for an LLM than a simple “chatbot in a box”. It also helps explain why behaviour can be powerful but hard to predict: the agent may open more tabs, run more code, or spawn more sub-tasks than a user expects. How it differs from chatbots and RPA/no-code tools Compared with a standard LLM chat interface (e.g. base ChatGPT), Manus: Maintains its own long-running workspace per task. Executes code and browser actions directly, not just describing them. Produces end artefacts like slide decks or simple apps, not just text. Compared with RPA or classic no-code automation, Manus: Is goal-driven rather than step-by-step flowchart driven. Does not guarantee deterministic, traceable flows. Offers less fine-grained control and governance than BPM or RPA suites. Meta acquisition and strategic backing Meta announced an agreement to acquire Manus in late 2025 at a reported price above US$2 billion and began integrating its agent capabilities into Meta AI products. In 2026, however, Chinese regulators moved to block and unwind the deal, and subsequent reporting indicates Meta has been separating Manus from its internal systems and “sunsetting” parts of the integration. Manus continues to be offered as a standalone agent service while the regulatory and corporate unwind process is underway Thorsten Meyer AI Sacra . For operators, the attempted acquisition and subsequent regulatory unwind create uncertainty: Meta’s involvement has validated Manus’s agent technology and raised its profile, but the forced separation and reports of sunsetting parts of the integration mean long‑term ownership structure and roadmap control remain unsettled rather than clearly anchored under Meta. Core capabilities: tasks Manus can actually execute Autonomous web research and synthesis Independent stress testing across 50+ tasks highlights Manus’s strength in open-ended web research, summarisation, and synthesis Botonomy AI . The agent can: Wide Research is Manus's own name for running many agents in parallel The browser operator is how Manus opens and acts on web pages inside its sandbox Manus documents generating working web apps from a single prompt Search, open, and navigate multiple sites in parallel. Extract relevant passages and data points. Compile structured reports, comparison tables, and executive summaries. One Reddit account describes research time reduced by around 80% for well-scoped tasks, with the caveat that costs were “ridiculously expensive” when left too open-ended Reddit . This aligns with the general pattern in user reports: Manus is effective for “good coverage and synthesis”, less so for perfectly reproducible, citation-grade workflows. Content and knowledge work Reviews consistently report Manus performing well at knowledge-intensive drafting from a single prompt AI IdeList Future Stack Reviews . Typical outputs include: Blog drafts and long-form articles. Pitch decks and presentation slide content. Emails, outreach sequences, and internal memos. Positioning docs, SOPs, and strategy briefs. Because Manus can browse and reference material live, it can weave in up-to-date examples and competitor mentions, then format them as slides or documents via its built-in slide maker and design workspace Future Stack Reviews . These outputs generally still need human editing, but they reduce the time spent on blank-page work. Lightweight coding and automation Manus is able to write and execute code inside its sandbox, and several reviews describe it building: Small utilities and scripts. Landing pages and simple web front-ends. Exploratory notebooks for data analysis AI IdeList . User reports characterise it as strong for “lighter coding tasks” but weak for complex software architecture or production-grade app builds without close human review Reddit . Attempts to delegating full Android mobile app builds, for example, are reported to fail, with missing glue code and structural issues. Data work: cleaning, analysis, and visualisation Within a single workspace session, Manus can load CSVs, clean and transform columns, generate charts, and perform first-pass analysis AI IdeList . Botonomy’s 50+ task review notes good performance on: Basic descriptive statistics. Outlier detection and data quality checks. Turning analysis into written briefs and slides Botonomy AI . The main limit is scope: once the data work demands complex joins, multi-step ETL pipelines, or repeatable jobs over changing data, Manus’s lack of determinism and orchestration visibility become constraints. Product and UX outputs Through its design workspace and web app builder, Manus can output: Figma-style design drafts for landing pages and simple flows. Static or lightly interactive marketing sites. Embedded tools or basic web apps deployed from a prompt Future Stack Reviews . Independent reviewers position these as prototypes and MVP-level outputs rather than production-ready SaaS backends or mobile apps Reddit . For founders, this makes Manus more useful as a rapid idea-validation tool than a full app factory. If your goal is “ship an MVP fast” rather than “experiment with a general agent,” AI app builders like Lovable or Bolt ( Lovable vs Bolt for MVPs ) are usually more predictable for getting a product in users’ hands. Manus Desktop (“My Computer”) for local workflows Manus offers a Desktop app that “brings Manus to your desktop” via a feature called My Computer, allowing the cloud‑hosted agent to work with local files and context Manus blog . According to the official docs, Desktop lets the agent access local files and context while still using Manus’s cloud models Manus docs . Documented and user-reported use cases include: Searching and summarising folders. Building briefs from internal PDFs, slides, and notes. Turning a personal knowledge base into new outputs. The Help Center explains that Desktop tasks consume credits based on factors such as the amount of data processed, the tools involved (for example, browser use or code execution), and the overall duration and complexity of the session Manus Help Center . A Reddit technical breakdown notes that Desktop felt fast and impressive for local file work, but noticeably slower and less predictable when using the browser via Desktop for web research Reddit . Connectors and integrations The Manus platform exposes connectors for API access, Zapier, Slack, Telegram, and Line, alongside web workspaces like a web-app builder, AI slide maker, design workspace, a browser operator that can use browser tabs, Wide Research mode, and a mail assistant Future Stack Reviews . In practice, this means Manus can be used as: A standalone workspace for one-off projects. An engine behind internal tools via API/Zapier. A co-pilot in communication channels (Slack/Telegram) for research and drafting. Where it breaks: limits, failure modes, and reliability Complex software projects and serious app builds Multiple user reports and reviews point to a clear limitation: Manus is not reliable for complex software projects such as mobile apps, production SaaS backends, or multi-service architectures Reddit . Reported issues include: Missing or incorrect glue code between components. No proper test suites or deployment pipelines. Architectural decisions made opaquely, with little traceability. Independent stress tests classify Manus as useful for repo-level exploration and small utilities, not as a drop-in “AI engineer” for complex systems Botonomy AI . If your roadmap involves serious app architecture, you’re usually better off pairing dedicated AI coding tools like Claude Code or Cursor with a stable backend such as Supabase ( Supabase review 2026 ) rather than leaning on a general agent for production-critical code. Determinism and reproducibility Reviewers flag that Manus cannot guarantee the same run twice, even with the same prompt Botonomy AI . Because the planner’s decisions and external web environment differ across runs, users see variation in: Which sources are used. The sequence of steps taken. Latency and total credits consumed. This matters if traceable, auditable workflows are required (for example, regulated financial or healthcare processes). For those contexts, simpler, deterministic orchestrations wrapped around LLM calls are often seen as safer. Long-running tasks, loops, and depth limits Independent tests and user stories describe Manus struggling with very long-running or open-scope goals Future Stack Reviews Botonomy AI . Common patterns include: Looping behaviour where the agent revisits similar pages or steps. Ambiguous stopping criteria leading it to “over-research” without clear added value. Loss of coherence on large multi-phase projects. These issues are closely tied to cost: more wandering means more browser and code-execution time, which means more credits burned. Cost hallucinations and agent overreach Several reviewers and users note that Manus sometimes “hallucinates” costs or simply runs far longer than anticipated, consuming many more credits than expected for a single task Future Stack Reviews . One independent review explicitly warns that credit consumption is hard to predict, especially when the agent spawns sub-tasks or continues exploring beyond implicit budget expectations Future Stack Reviews . This overreach is part of the autonomy trade-off: a goal-driven planner optimises for task completion, not a specific credit budget, unless the task is explicitly constrained. Overall reliability by category Aggregating independent tests and user accounts yields a rough picture: Strong: open-ended research, summarisation, first-draft content; parallel web research and synthesis are recurring strengths Botonomy AI . Moderate: small coding tasks, data analysis within a single session, slide design, and simple web apps. Weak: complex app architecture, strict SLAs, regulated workflows, and anything where reproducibility is a requirement. Pricing and credits: what you actually pay The hybrid subscription + credits model Sacra’s equity research describes Manus as a subscription business with usage-based pricing layered on top: membership tiers plus credit consumption for actual agent execution Sacra . The official Help Center confirms a membership pricing structure and, as of August 13, 2026, publicly lists a Pro plan starting from US$20/month (with a discount for annual billing); additional plan prices and regional variants appear in logged-in or geo-specific pricing views and can change over time Manus Help Center . Manus tiers at $20, $40 and $200 a month, each with a monthly credit allowance included In practical terms, that means: A monthly fee for access (plan names and prices can vary over time and by region). Additional charges via credits as the agent works; heavier, longer tasks cost more. If you’re benchmarking total AI spend across tools, it’s useful to compare Manus’s hybrid structure with more transparent per-token or per-seat pricing from models like ChatGPT and Claude ( ChatGPT pricing 2026 , Claude pricing 2026 ), or with app builders that wrap infra costs into fixed plans ( Lovable pricing 2026 ). How credits are consumed (especially on Desktop) The Desktop Help Center article explains that tasks consume credits based on factors such as the amount of computation and LLM usage required, the volume of data processed, and the tools invoked (for example, browser usage, code execution, or multi-file operations). Longer, more complex sessions that make heavier use of these tools consume more credits than short, simple ones Manus Help Center . The same article notes that Desktop tasks can consume “significantly more credits” for long sessions, parallel subtasks, or heavy browser usage compared with short, single-file operations Manus Help Center . However, it does not map credits directly to per-minute or per-token dollar costs, making forecasting difficult. Pricing table (what is publicly knowable) Item Details As-of date Source Membership plans (general) Manus uses a subscription model with multiple plans plus usage-based credits. As of August 13, 2026, the Help Center publicly lists a Pro plan starting from US$20/month (with a discount for annual billing); other tiers and regional pricing may differ and can change over time. 2026-08-13 Manus Help Center Business model Subscription plus usage-based pricing (credits) layered on top of monthly subscriptions for individuals and teams. 2026-05-25 Sacra Historical consumer tiers (indicative) User reports mention historical "Standard" and "Pro" tiers with charges such as ~US$39/month for a Standard plan, but these numbers are not reliable indicators of current pricing. 2025-04-29 Reddit High-end tier example Billing-issue report of a hard-locked modal demanding an upgrade to a US$4,999.99/month tier to resume access; may reflect a bug but evidences at least one very high-priced tier. 2026-06-13 Reddit Desktop credit usage Credits consumed per task, with heavier browser use, code execution, more data processed, and long sessions burning more; credit-to-currency mapping depends on the underlying plan. 2026-04-10 Manus Help Center User complaints and cost risk User reports highlight that Manus’s hybrid pricing can lead to unexpected bills when the agent is used heavily or without guardrails: Reports on Reddit of individual users being charged hundreds of US dollars in a single month under credit-based billing Reddit . At least one long, detailed Reddit post describing a monthly charge of roughly US$89,000 tied to high credit consumption Future Stack Reviews . Billing issues, including a user-reported glitch where the web app displayed a hard‑locked modal requesting an upgrade to a roughly US$4,999.99/month tier before access could resume, which the user says required support intervention Reddit . These are user anecdotes, not audited financial data, but they demonstrate the potential for large bills if credit usage is not monitored. Practical cost guardrails for founders Given the opacity, teams adopting Manus typically need to implement their own guardrails, for example: Set hard monthly spend caps at the account or card level. Constrain prompts by scope (for example, “90 minutes of research”, “max 10 sources”). Start with small, well-defined tasks and inspect logs for credit spikes. Require human checkpoints between major phases of long tasks. Testing Manus against its marketing: scenario benchmarks Independent reviews and user stories collectively cover a range
 Manus presents itself as a general agent that executes tasks rather than just replying
 Wide Research is Manus's own name for running many agents in parallel
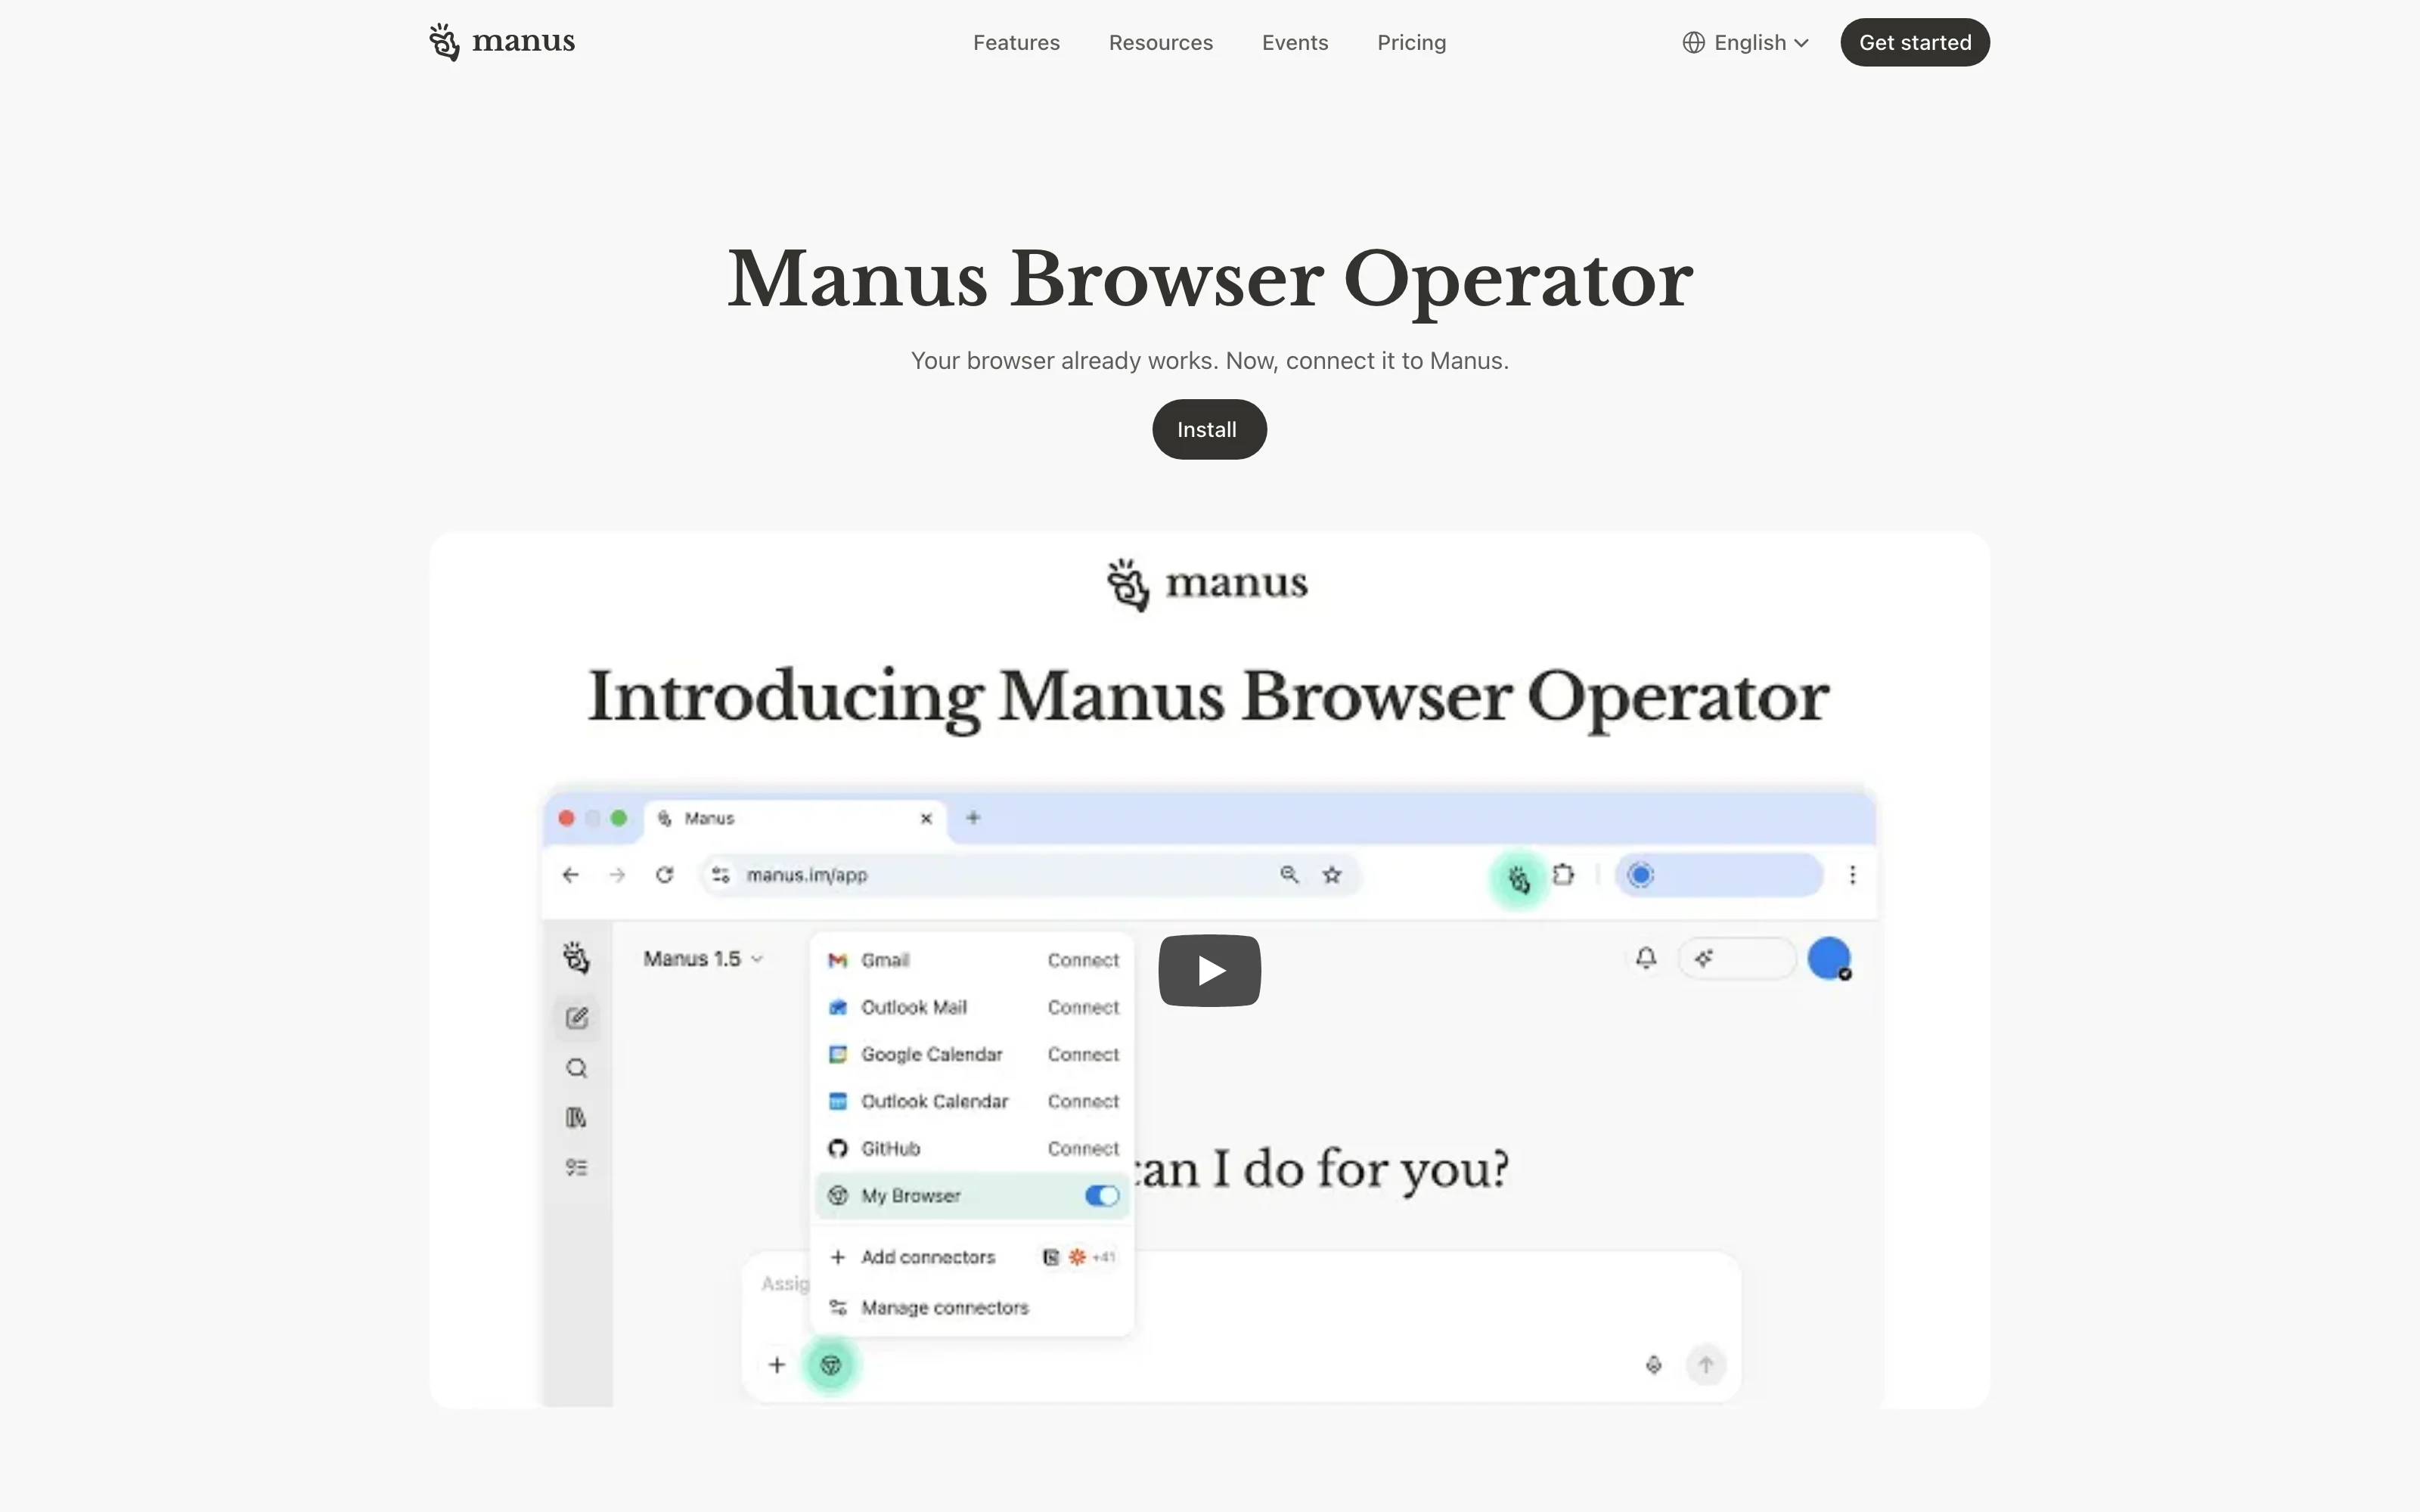 The browser operator is how Manus opens and acts on web pages inside its sandbox
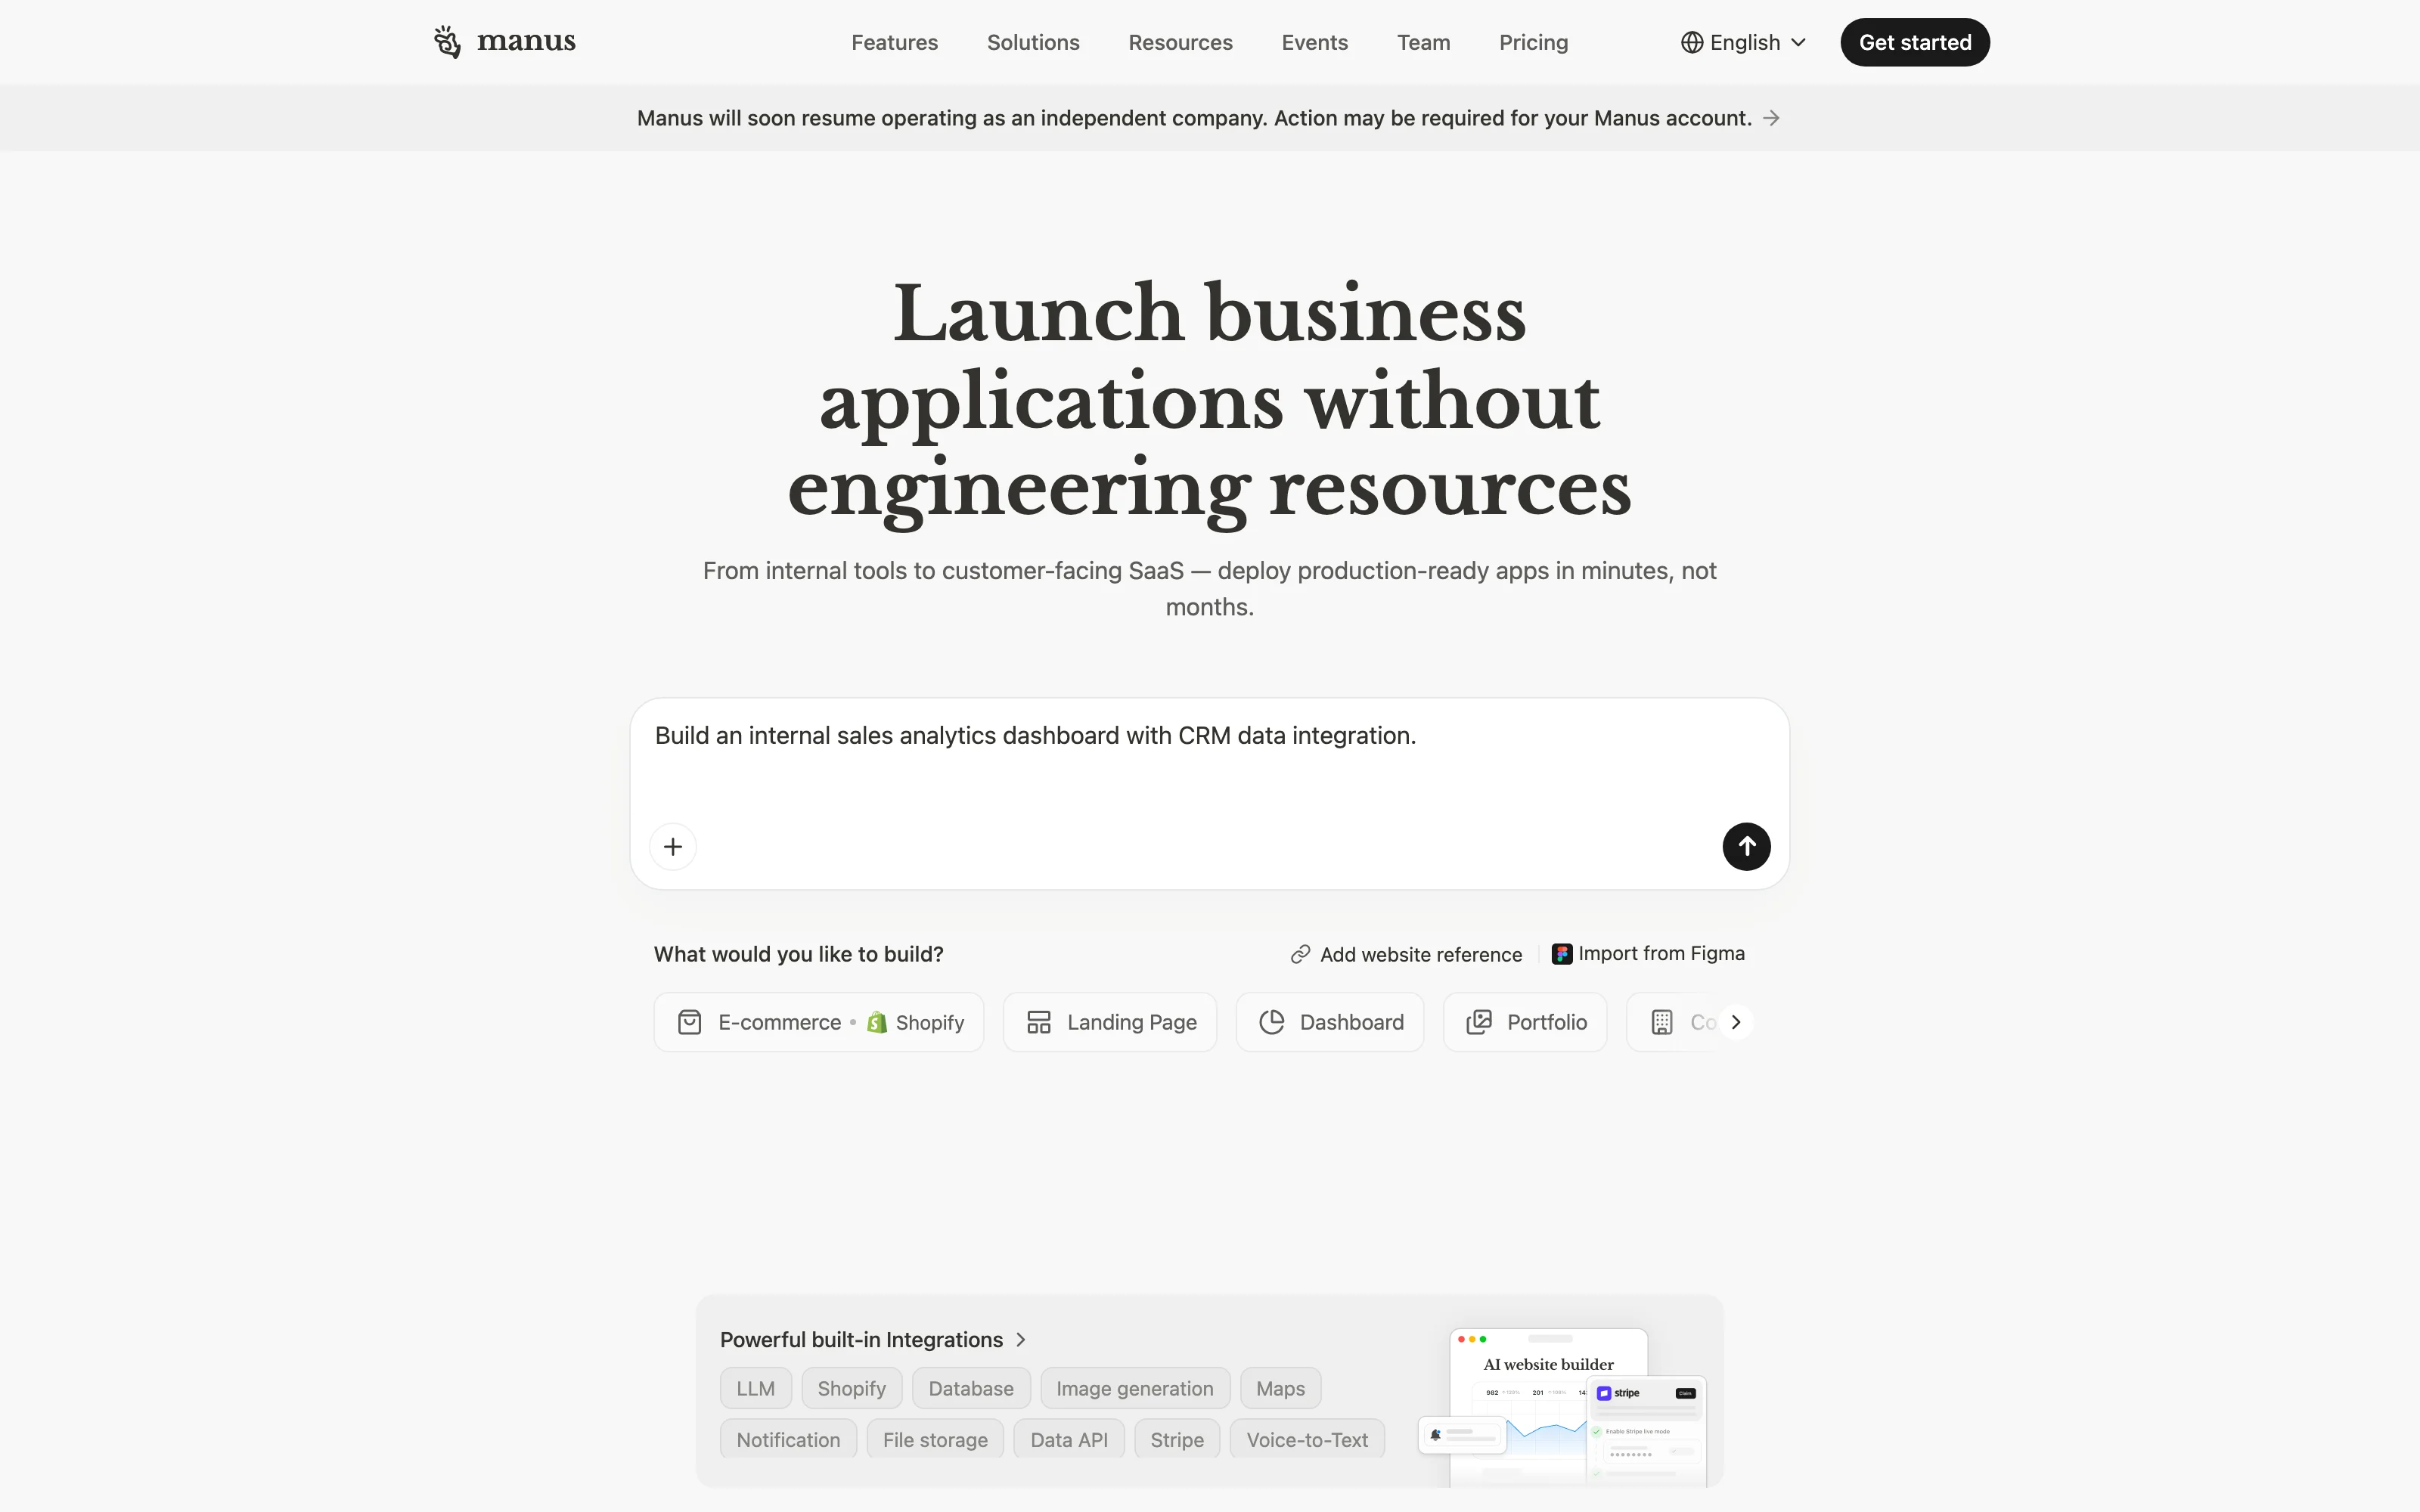 Manus documents generating working web apps from a single prompt
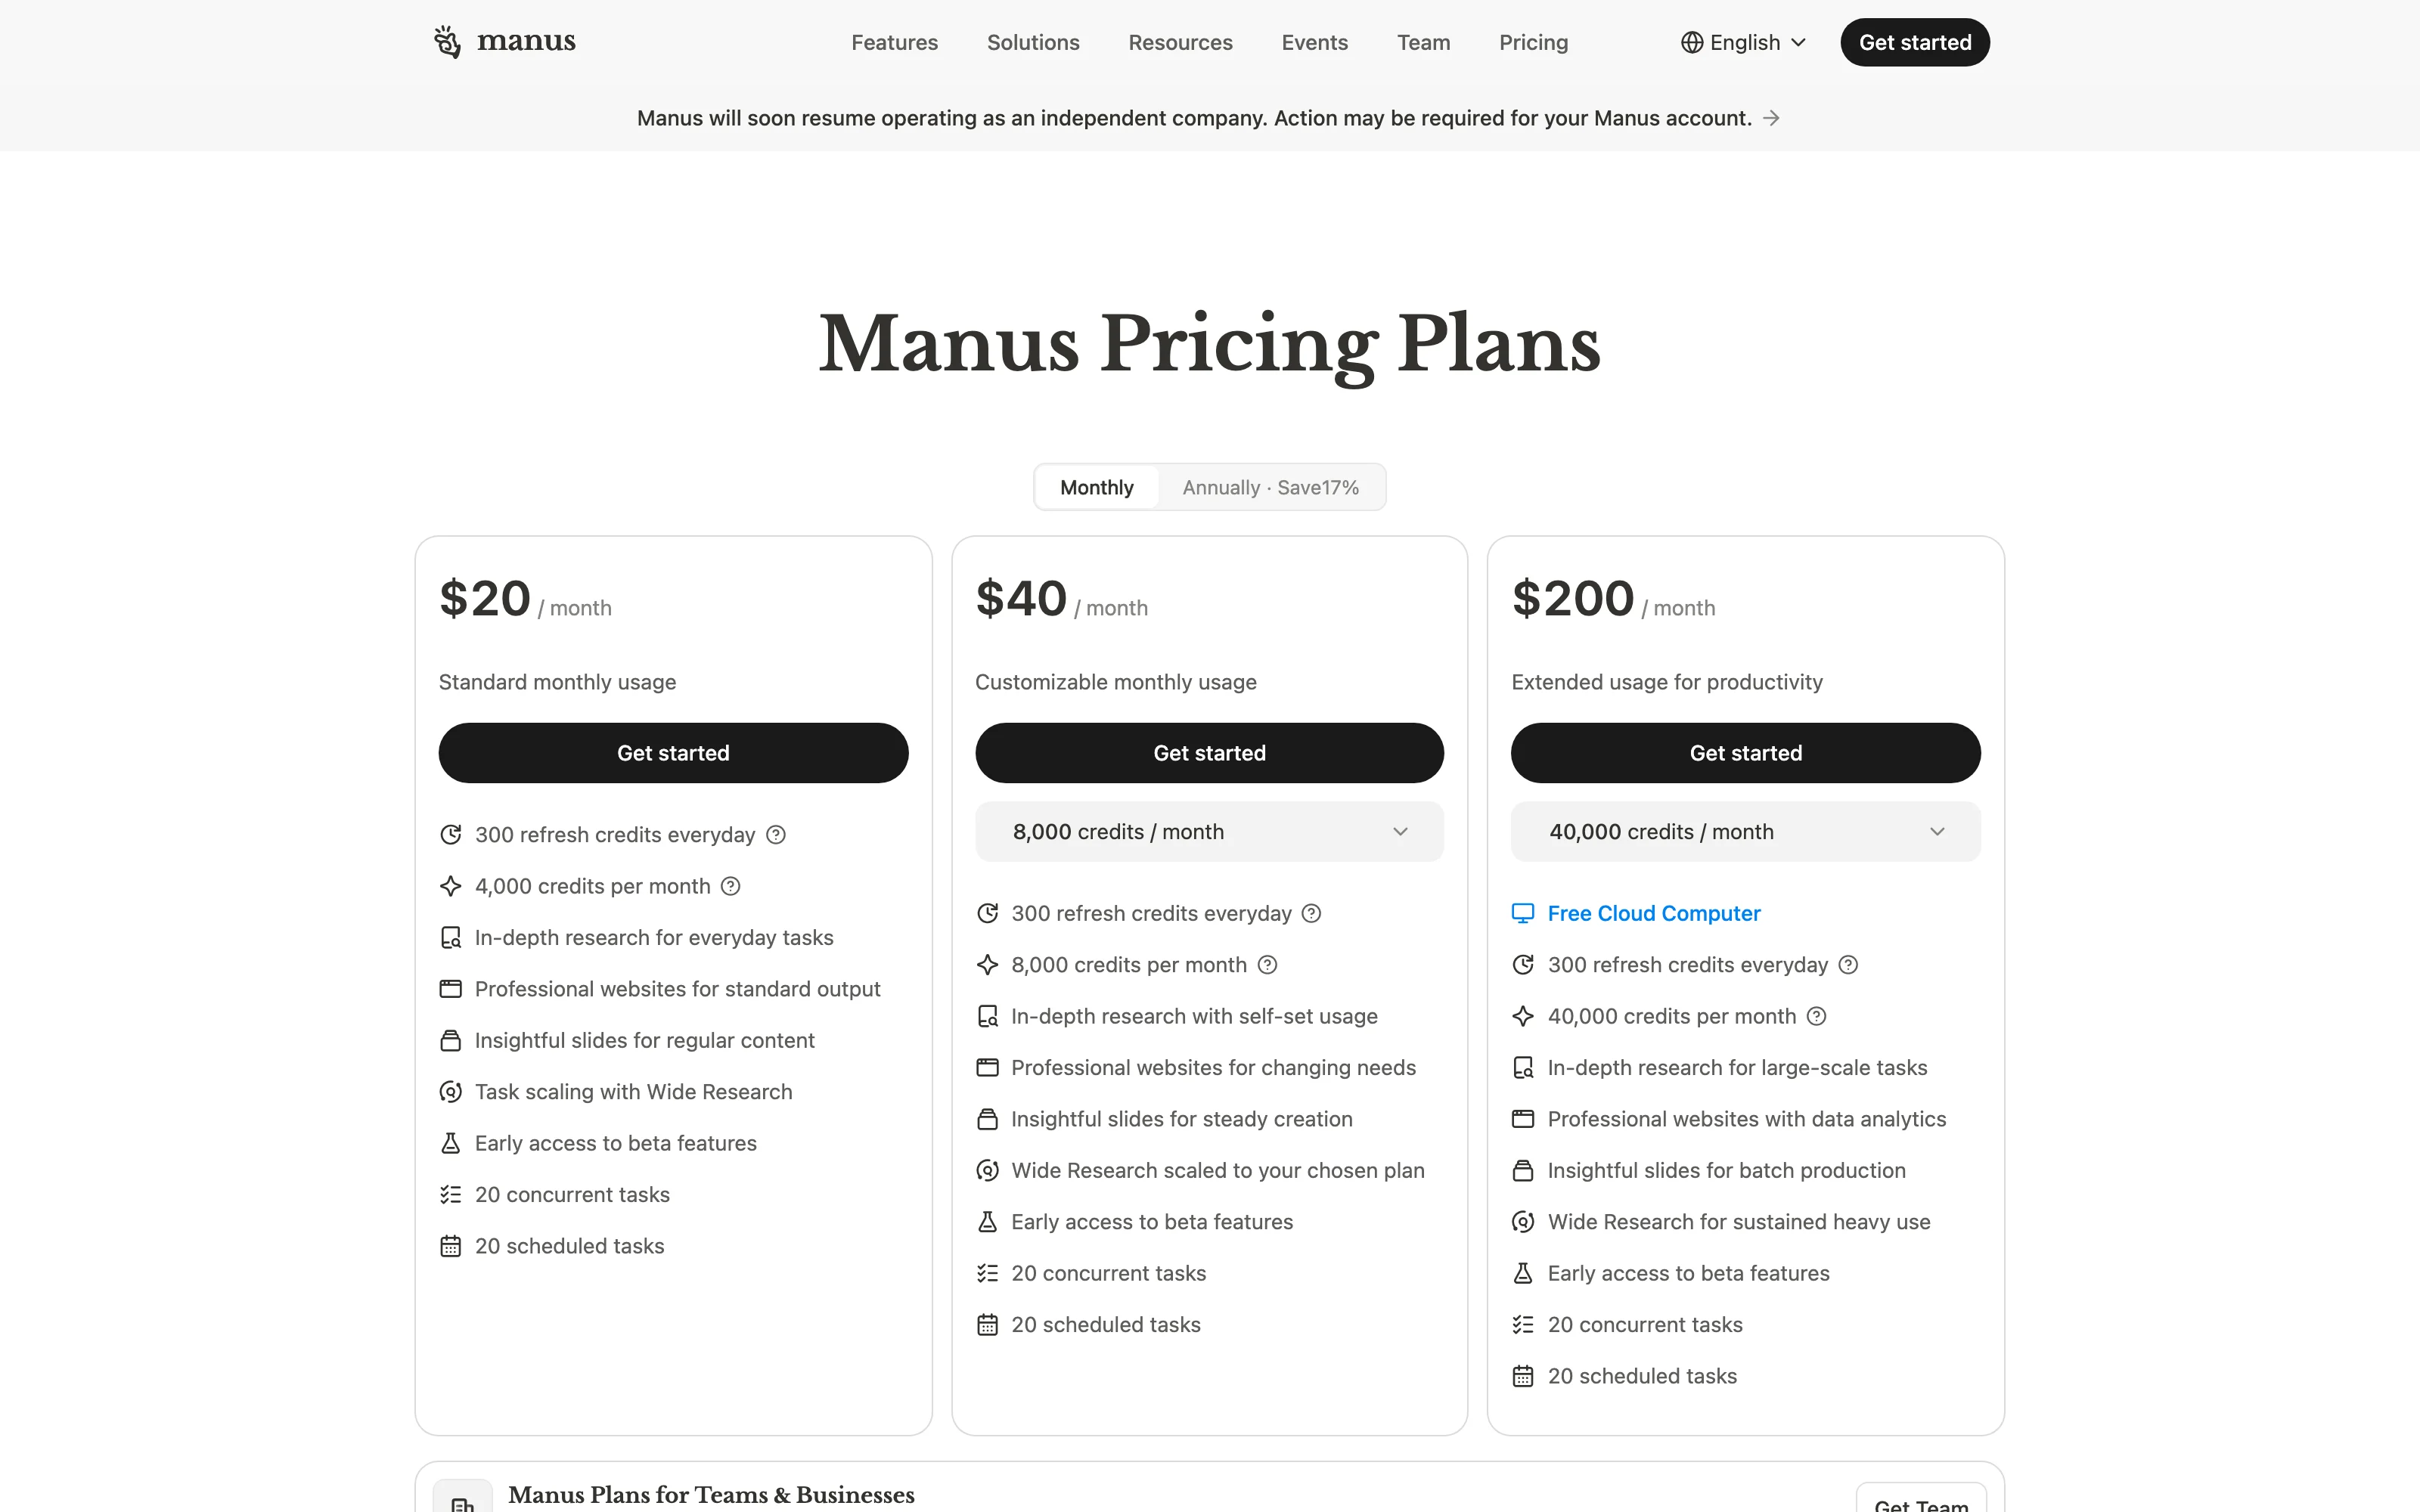 Manus tiers at $20, $40 and $200 a month, each with a monthly credit allowance included
Browse the site
Home
about
story
work
expertise
ai
ai ai product development
ai ai agents
ai ai automation
ai ai consulting
ai arabic ai products
ai kuwait
toolkit web
toolkit claude
toolkit lovable
toolkit notion
toolkit webflow
toolkit shopify
toolkit wordpress
toolkit ai solutions
services
services business strategy
services growth planning
tools
blog
listening
books
stack
contact
quote
privacy
terms