AI App Builders for Internal Tools (Not Your Core Product)
How to turn AI app builders into real ops dashboards and admin panels without hiring engineers, and where to draw the line before you need a dev team.
Quick verdict: where AI builders actually work for internal tools AI app builders are now good enough to ship focused internal tools without an engineering team, as long as teams stay inside a realistic scope: Best for : CRUD dashboards, admin panels, support/refund consoles, simple CRMs, approval queues, and back-office reporting. Avoid if : complex business rules, low-latency realtime, heavy integrations, or regulated flows (payroll, health, KYC) are required in production. Starting cost : typically tens of US dollars per month in seats, plus AI credits. Costs spike fast once 24/7 automations are enabled. Main strength : operators can go from problem statement to working UI over live data without touching code or provisioning infra. Main limitation : durability – data models, permissions, and logic become hard to manage as complexity grows; many teams later migrate to a more traditional stack. 1. Why internal tools are finally feasible without an engineering team Internal tools are the unglamorous backbone of operations: refund consoles, admin panels, approval workflows, basic CRMs, and ops dashboards. Historically they required engineers to: Model data (CRUD on production databases). Implement permissions (who can see/edit what). Build and host bespoke UIs. That work competed with customer-facing roadmap, so ops teams often waited months for relatively simple tools. Modern AI app builders change the equation. Products such as UI Bakery explicitly target internal tools and admin panels, combining AI-generated UIs with visual editing and database/API connections for dashboards and CRUD apps UI Bakery . Taskade Genesis lets non-technical users describe an internal app in natural language and generates a live tool with UI, data structures, and automations on top of Taskade’s AI-native workspace Taskade . Lovable generates full‑stack web apps from prompts, with in‑app code editing and deployment, using a real-code stack documented in its platform and docs Lovable . The new build-vs-buy line looks roughly like this: Buy SaaS when there is a strong, opinionated product for a given function (e.g. Zendesk, HubSpot, specialised WMS). Build with AI when company-specific workflows exist that generic SaaS cannot model without extreme workarounds. In practice, many teams prototype these flows in Lovable, then graduate to a more durable stack once the patterns stabilise – see the best AI development stack for 2026 for migration paths. For most teams, AI builders are best treated as a way to ship narrow, high-leverage internal tools fast – not a replacement for core product engineering. 2. What “AI app builder” actually means now “AI app builder” covers two broad approaches: Prompt-to-app generators – users describe the app in natural language, the platform generates UI, database, and basic logic end-to-end. Examples include Taskade Genesis Taskade , Figma Make Figma , and Chirai Chirai . Visual builders with an AI copilot – users still work with a visual editor and data connectors, but AI drafts components or code snippets. UI Bakery positions its AI engine directly for internal tools and dashboards UI Bakery . Under the hood, many internal-tool builders bundle: a database or model layer (tables, relationships), authentication and at least basic role-based access control (RBAC), data connectors to common APIs/DBs (e.g. Postgres, Stripe, Shopify), workflows/automations (triggers, actions, sometimes agents), and hosting, deployment, and environment management. Multiple reviews point out that many builders nail the UI demo but struggle once robust data persistence, cross-table relationships, and more complex state and logic are required Softr Reddit . The generated UI can be treated as scaffolding; the real work lies in tightening the schema and workflows. Credit-based billing: why it matters for ops Credit-based billing is now common across AI app builders. As of March 2026, Taskade’s Billing and Pricing FAQ and Genesis FAQ describe a Pro plan including 50,000 AI credits per month for up to 10 users, at US$20/month on monthly billing or US$16/month on annual billing; the live pricing page should always be checked for current details Taskade . Community reports indicate that Genesis-heavy workloads can quickly exhaust credits, with some users noting that automations on paid accounts consumed the allowance within hours Reddit . Lovable uses credits for building and running apps in its cloud environment. Its published plans are Free at $0/month, Pro at $25/month and Business at $50/month, with both paid tiers carrying 100 monthly credits plus credit rollovers, on-demand top-ups and per-member credit limits; Enterprise is a volume-based platform fee. Effective per-credit rates still change, so confirm them on the pricing page at the time of purchase Lovable . Community discussions note that complex rebuilds can consume many credits rapidly Reddit . If you’re budgeting a serious Lovable rollout, the detailed breakdown in Lovable Pricing 2026 will help you avoid surprise overages. Implication for internal tools: UI usage is typically cheap, complex automations are not . A simple CRUD dashboard over a database may stay within included credits, while agent-style, multi-step flows can reach high credit usage in days. 3. Choosing the right AI builder for ops and admin use cases Before picking a tool, clarify who will own it and their skill level: Ops or support manager : comfortable with spreadsheets and dashboards, not code. Technical PM / data-savvy analyst : fine with SQL, APIs, basic JSON. Part-time engineer : can read and edit generated code if needed. This directly informs which archetype to prefer. Tool archetypes and where they fit Internal-tool-first builders Tools like UI Bakery focus on internal dashboards, admin panels, and CRUD apps, with AI used to speed up UI and query generation UI Bakery . They generally offer strong data connectors and permissions, and suit teams that already understand their data model. Prompt-first generators Lovable generates full‑stack web apps from prompts and exposes real code that can be edited Lovable . Chirai markets directly to non-technical founders to build internal tools and portals from natural language Chirai . These are useful when a working prototype is needed quickly, with the option to export or refactor code later. For a deeper look at where Lovable shines (and where it breaks down for long-term stacks), see the Lovable review . Workspace-native builders Taskade Genesis lives inside a broader collaboration and task platform, and focuses on internal business tools where AI agents and automations are wired together Taskade . This model fits teams already using Taskade for projects who want embedded internal tools. Design-native builders Figma Make turns natural language prompts into interactive web apps, including dashboards and admin panels, from within the Figma ecosystem Figma . This suits design-led teams that want to go from mockup to working app without switching tools. Data posture: where does the truth live? Two main patterns are practical: Greenfield internal DB : use the builder’s built-in database for operational tools with their own data (e.g. internal checklists, lightweight CRM). This is easiest to set up, but backup and export need to be planned. Connected to existing systems : use connectors to Stripe, Shopify, Postgres, etc. Builders like UI Bakery and comparable tools support read/write via authenticated connections UI Bakery . A safe pattern is “read-wide, write-narrow” : allow broad read access for context, but restrict write actions to a small set of well-reviewed operations. Compliance and access Many AI-first builders lag behind mature internal-tool platforms on SSO, granular RBAC, audit logs, and IP restrictions. Before adopting one as a core console, validate: SSO/SAML or at least SCIM-compatible user management. Field-level or row-level permissions for sensitive data. Action logs and exportable audit trails. Data residency options (especially relevant in EU and GCC contexts). 4. Scoping: what can realistically be built without engineers Most non-technical teams tend to over-scope their first internal app. A practical rule is: one core workflow per app . Good fits for AI-built internal tools Refund and credit consoles. Internal ticket triage and queues. Inventory or order exception dashboards. Field ops checklists and visit logs. Simple partner or vendor portals. Basic CRMs and contact management tools. Reporting and monitoring dashboards over existing data. These all share a pattern: structured data + simple workflows . The logic is usually linear, and edge cases can be handled by manual overrides. Borderline and bad fits Borderline (possible, but expect complexity): Multi-tenant admin for a customer-facing SaaS. Complex SLA rules spread across many systems. Heavy realtime collaboration (multiple users editing shared state at once). Bad fits (best avoided for now): Low-latency trading or pricing systems. Deeply regulated flows (payroll, health, KYC) without a security review. Anything requiring bespoke algorithms or optimisers. Write a one-page spec the AI can work with Before prompting an AI builder, capture a one-page spec covering: Outcome : e.g. “Cut refund handling time from 20 minutes to 5.” Actors : support agents, team leads, finance. Data sources : e.g. Stripe charges, Shopify orders, internal tickets. Views : list view, detail view, approval queue, simple analytics. Allowed actions : create/update records, trigger webhook, send email. Permissions : who can read, who can write, who can approve. This spec becomes the backbone of the prompt and reduces AI hallucination. 5. Workflow: from prompt to production for an ops dashboard Step 1 – Quantify the problem Select one workflow where time is clearly wasted. Example: “Support refunds currently consume 8 agent-hours per week, jumping between Stripe, spreadsheets, and email.” Lovable's built-in backend covers database, auth, storage and edge functions, with a step-by-step CRM tutorial in the same docs Step 2 – Map the data List the systems involved and whether the tool must read or write: System of record : Stripe for charges; Shopify for orders; ticketing system for customer context. Reads : list orders, show payment history, display previous tickets. Writes : issue partial or full refunds, mark tickets as resolved, log reason codes. Plan to give the builder read access to everything needed , and write access only to a handful of actions . Step 3 – Choose the builder If a non-technical ops lead will own it : favour internal-tool-first visual builders (e.g. UI Bakery-class) or workspace-native (Taskade Genesis) where fields and workflows can be managed visually. If a technically fluent owner is available : prompt-first tools like Lovable are viable; code can later be exported to GitHub and moved to platforms such as Supabase/Vercel or similar when the hosted runtime is outgrown Reddit . For a production-ready migration path, see the Lovable + Supabase production setup . Step 4 – Draft a strong natural-language brief Provide the builder with something close to the one-page spec. Example: “Create an internal refunds console for support agents. Connect to Stripe (read charges and customers) and Shopify (read orders). Agents should see a list of recent orders, filter by email, order ID, and status, and open a detail view with payment history. They can propose a partial or full refund with a reason code, but only team leads can approve and execute refunds. Log all actions with user, timestamp, and reason. Include a simple analytics page showing refund volume by product and by reason over time.” Many AI builders can generate an initial schema, UI, and flow from this level of detail Softr UI Bakery . Step 5 – Tighten the schema Once the app is generated, review: Tables and fields: are the right entities present (orders, payments, refunds, reasons)? Relationships: e.g. one order to many payments, one refund to one payment. Constraints: maximum refund amount, allowed statuses, required reason codes. This is where a data-savvy owner adds value. Several builders allow tables to be adjusted visually and then ask the AI to update UI and logic accordingly. Step 6 – Permissions and guardrails Configure: Roles (agent, lead, admin). Read vs write constraints (agents propose, leads approve). Action logging (who did what, when, and with which payload). Environment separation (connect to staging Stripe/Shopify until the configuration is stable). For sensitive flows, it is safer to adopt a human-in-the-loop pattern: agents or bots prepare actions, but a senior operator approves. Step 7 – Pilot, then iterate Roll out to 3–5 users for 2–4 weeks. Track: average handling time, number of refunds processed, error/rollback rate. Add features only when they address observed bottlenecks; avoid unnecessary AI-suggested additions. 6. Example walkthrough: refunds and credits admin panel This section outlines a realistic build path for a refunds tool using an AI app builder that supports internal dashboards and CRUD (e.g. UI Bakery-class or Lovable-class platforms). It is illustrative rather than tied to a specific vendor UI. Before state Support agents log into Stripe to issue refunds. They update a shared spreadsheet to track credits. Approvals are handled via Slack or email. There is no clear analytics view on refund volume or reasons. Model the data Customers : id, email, name, segment. Orders : id, customer_id, total, status, created_at. Payments : id, order_id, processor (Stripe), amount, status. Refunds : id, payment_id, amount, reason_code, status (proposed/approved/rejected/executed), created_by, approved_by, created_at. Reason codes : id, label, category (product/fulfilment/billing/other). Scaffold CRUD views and filters Use the builder’s AI or visual editor to create: A Refund queue view : table of orders/payments with filters by status, amount, date, and email. A Detail drawer : customer info, order items, payment history, prior tickets. A Refund creation form : amount, reason code, free-text note. Tools like UI Bakery explicitly support operations dashboards and analytics views using charts and widgets without needing a BI engineer UI Bakery , which suits this pattern. Implement approval workflow Configure a simple internal flow: Agents can create refunds with status = proposed . Leads see a Pending approvals view with filters and bulk actions. On approval, the app calls a backend action to hit Stripe’s refund API and sets status = executed . On rejection, the app records status = rejected with a note. Many AI builders allow wiring actions back to source systems via authenticated connectors, as long as a narrow set of write operations is defined UI Bakery . Add basic analytics Build a dashboard with: Refund amount over time (daily/weekly/monthly). Refunds by product or category. Refunds by agent (to identify training needs). Top reason codes. This is typically a matter of pointing chart widgets at the Refunds table and configuring groupings. Rollout and monitoring Run in staging mode for a week: simulate refunds or cap amounts. Switch to production with limits (e.g. auto-approve under US$20, manual review above). Review weekly: refund volume, reasons, and any manual corrections. 7. Example: ecommerce fulfilment ops dashboard This example sketches a fulfilment operations dashboard built via an AI app builder with API connectors. Inputs Shopify (or equivalent) : orders, fulfilment status. 3PL API : shipment status, tracking numbers. Ticketing system : customer complaints or delivery issues. Spreadsheet (optional): manual exceptions or special handling notes. Unified dashboard The app should offer: Global search by order ID, email, or tracking number. Filters for unfulfilled, delayed, or problematic orders. An exceptions queue : orders delayed beyond SLA, mismatched statuses between Shopify and 3PL, or repeated complaints. Safe internal actions Mark order as shipped (write to Shopify). Resend confirmation email. Escalate to warehouse or 3PL via task/ticket creation. Initial actions should be reversible and low-risk. Deep integrations (e.g. re-routing shipments, carrier-level rule changes) are better handled via the core stack once patterns are stable. Handling latency and sync Some delay should be expected: the dashboard is only as fresh as the API polling or webhook events allow. For internal ops, “near realtime” (e.g. a few minutes) is often enough; sub-second trading-desk behaviour should not be assumed. What to exclude from v1 Inventory forecasting or purchasing decisions. Carrier optimisation and cost-minimisation logic. Automated refund or reshipment rules without human oversight. 8. Data, security, and compliance that cannot be ignored AI builders are cloud platforms. Production data will pass through or reside on their infrastructure, including logs. Before connecting Stripe, HR, or health data, clarify: Supabase's rule for internal tools: RLS must be enabled on every table in an exposed schema, with the SQL to do it Where data lives : regions, sub-processors, and backups. What is logged : requests, payloads, AI prompts/responses, and retention periods. Access controls : role definitions, row/field-level security. Export options : whether data, schemas, and (ideally) code can be extracted if migration is needed. For early tools, a pragmatic stance is to work with staging environments and avoid direct access to highly regulated data until a security or compliance team signs off. Questions to send to vendors Which regions can workspaces be hosted in? Are logs replicated globally? Is SSO/SAML and SCIM supported for user lifecycle management? How is RBAC implemented? Can actions be restricted by role and environment? Can schemas, workflows, and data be exported in a machine-readable format? What happens to data if the account is downgraded or cancelled? 9. Cost model: credits, seats, and when to call in an engineer Budget along two axes: Lovable's plans: Free, Pro at $25/month and Business at $50/month, each paid tier carrying 100 monthly credits Seats : per-user or per-workspace fees vary by vendor. For example, UI Bakery and Taskade both price core builder seats in the tens of US dollars per month, with additional viewer or end-user allowances documented on their pricing pages UI Bakery Taskade . AI usage : credits or “runs” consumed by generations, automations, and agent reasoning. Light use may stay within included credits; heavy automation rarely does Taskade Reddit . Plan / Product Price & structure Notes As-of date Taskade Pro US$20/month when billed monthly; US$16/month when billed annually; includes 50,000 AI credits/month and 10 included users Credits used for Genesis app builds and automations Taskade March 2026 As internal tools succeed, two things usually happen: Usage grows – more ops and support staff rely on the tool daily. Requirements harden – you need stricter SLAs, custom logic, and deeper integrations. At that point, it often becomes cheaper and safer to involve an engineer or move to a more robust stack, keeping the AI builder as a prototyping environment. If you’re deciding when to graduate out of AI builders entirely, the stage-by-stage guidance in the best AI coding stack short list and broader 2026 AI development stack guide will help you pick the right tools for MVP versus production.
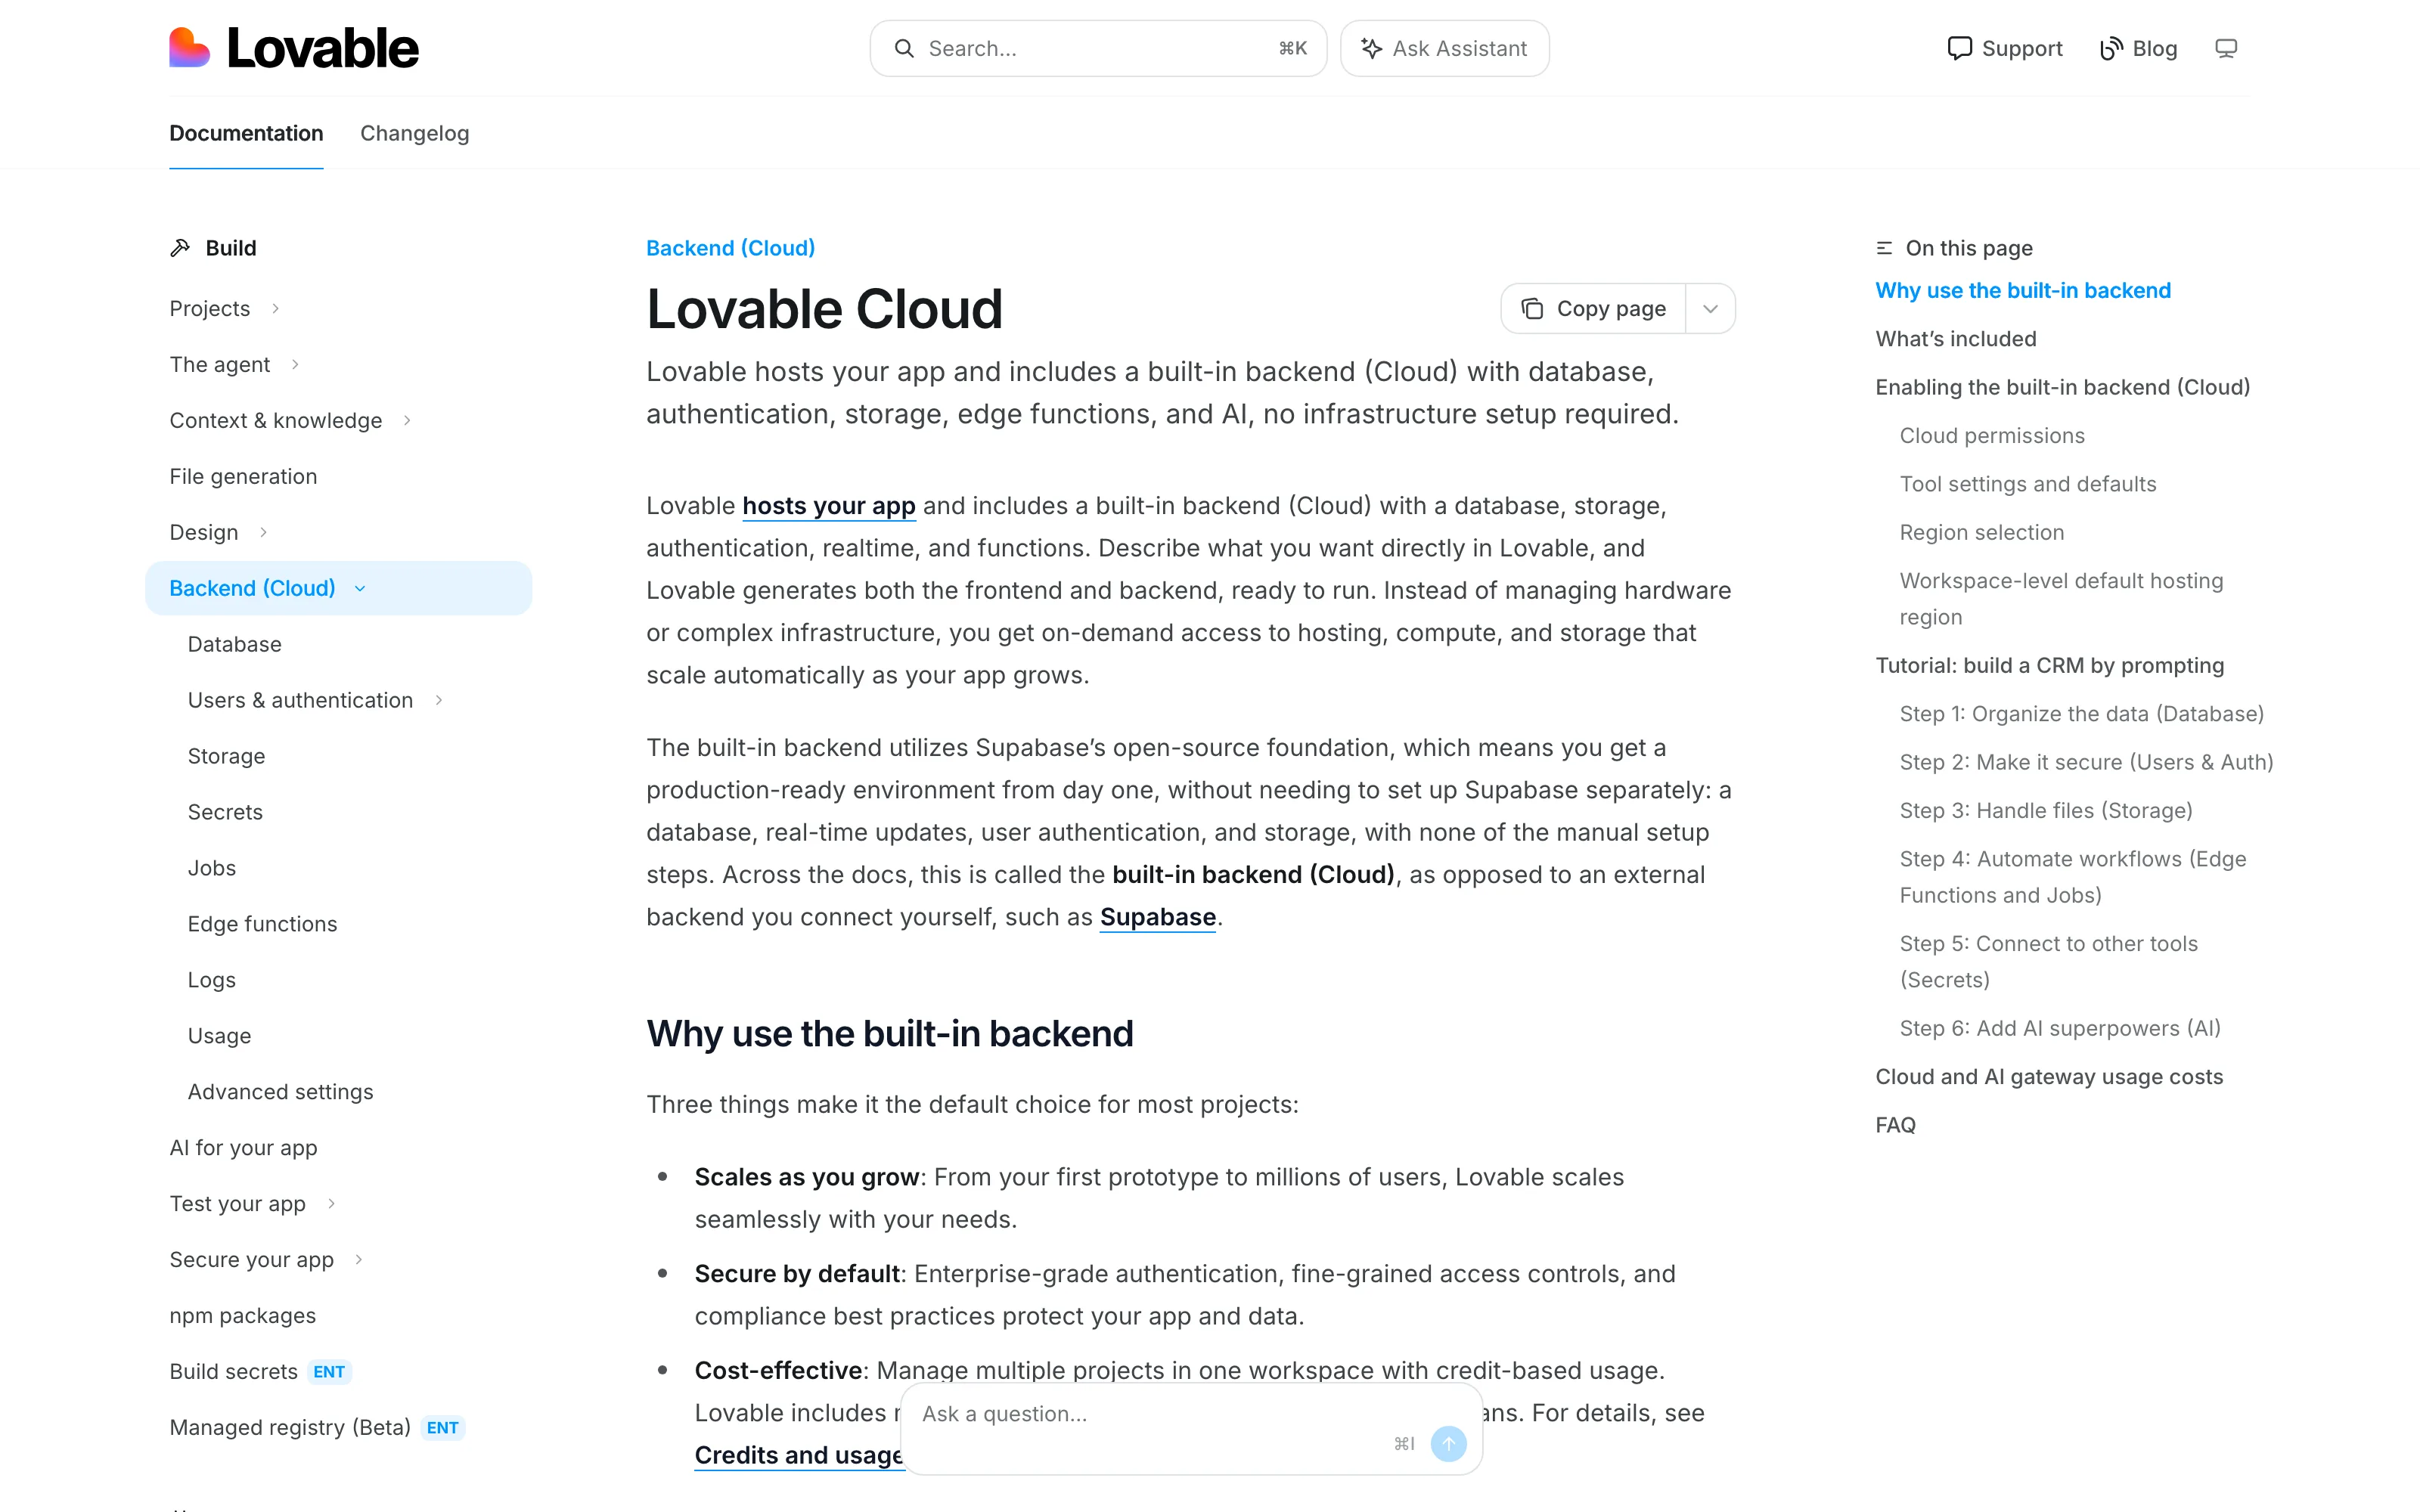 Lovable's built-in backend covers database, auth, storage and edge functions, with a step-by-step CRM tutorial in the same docs
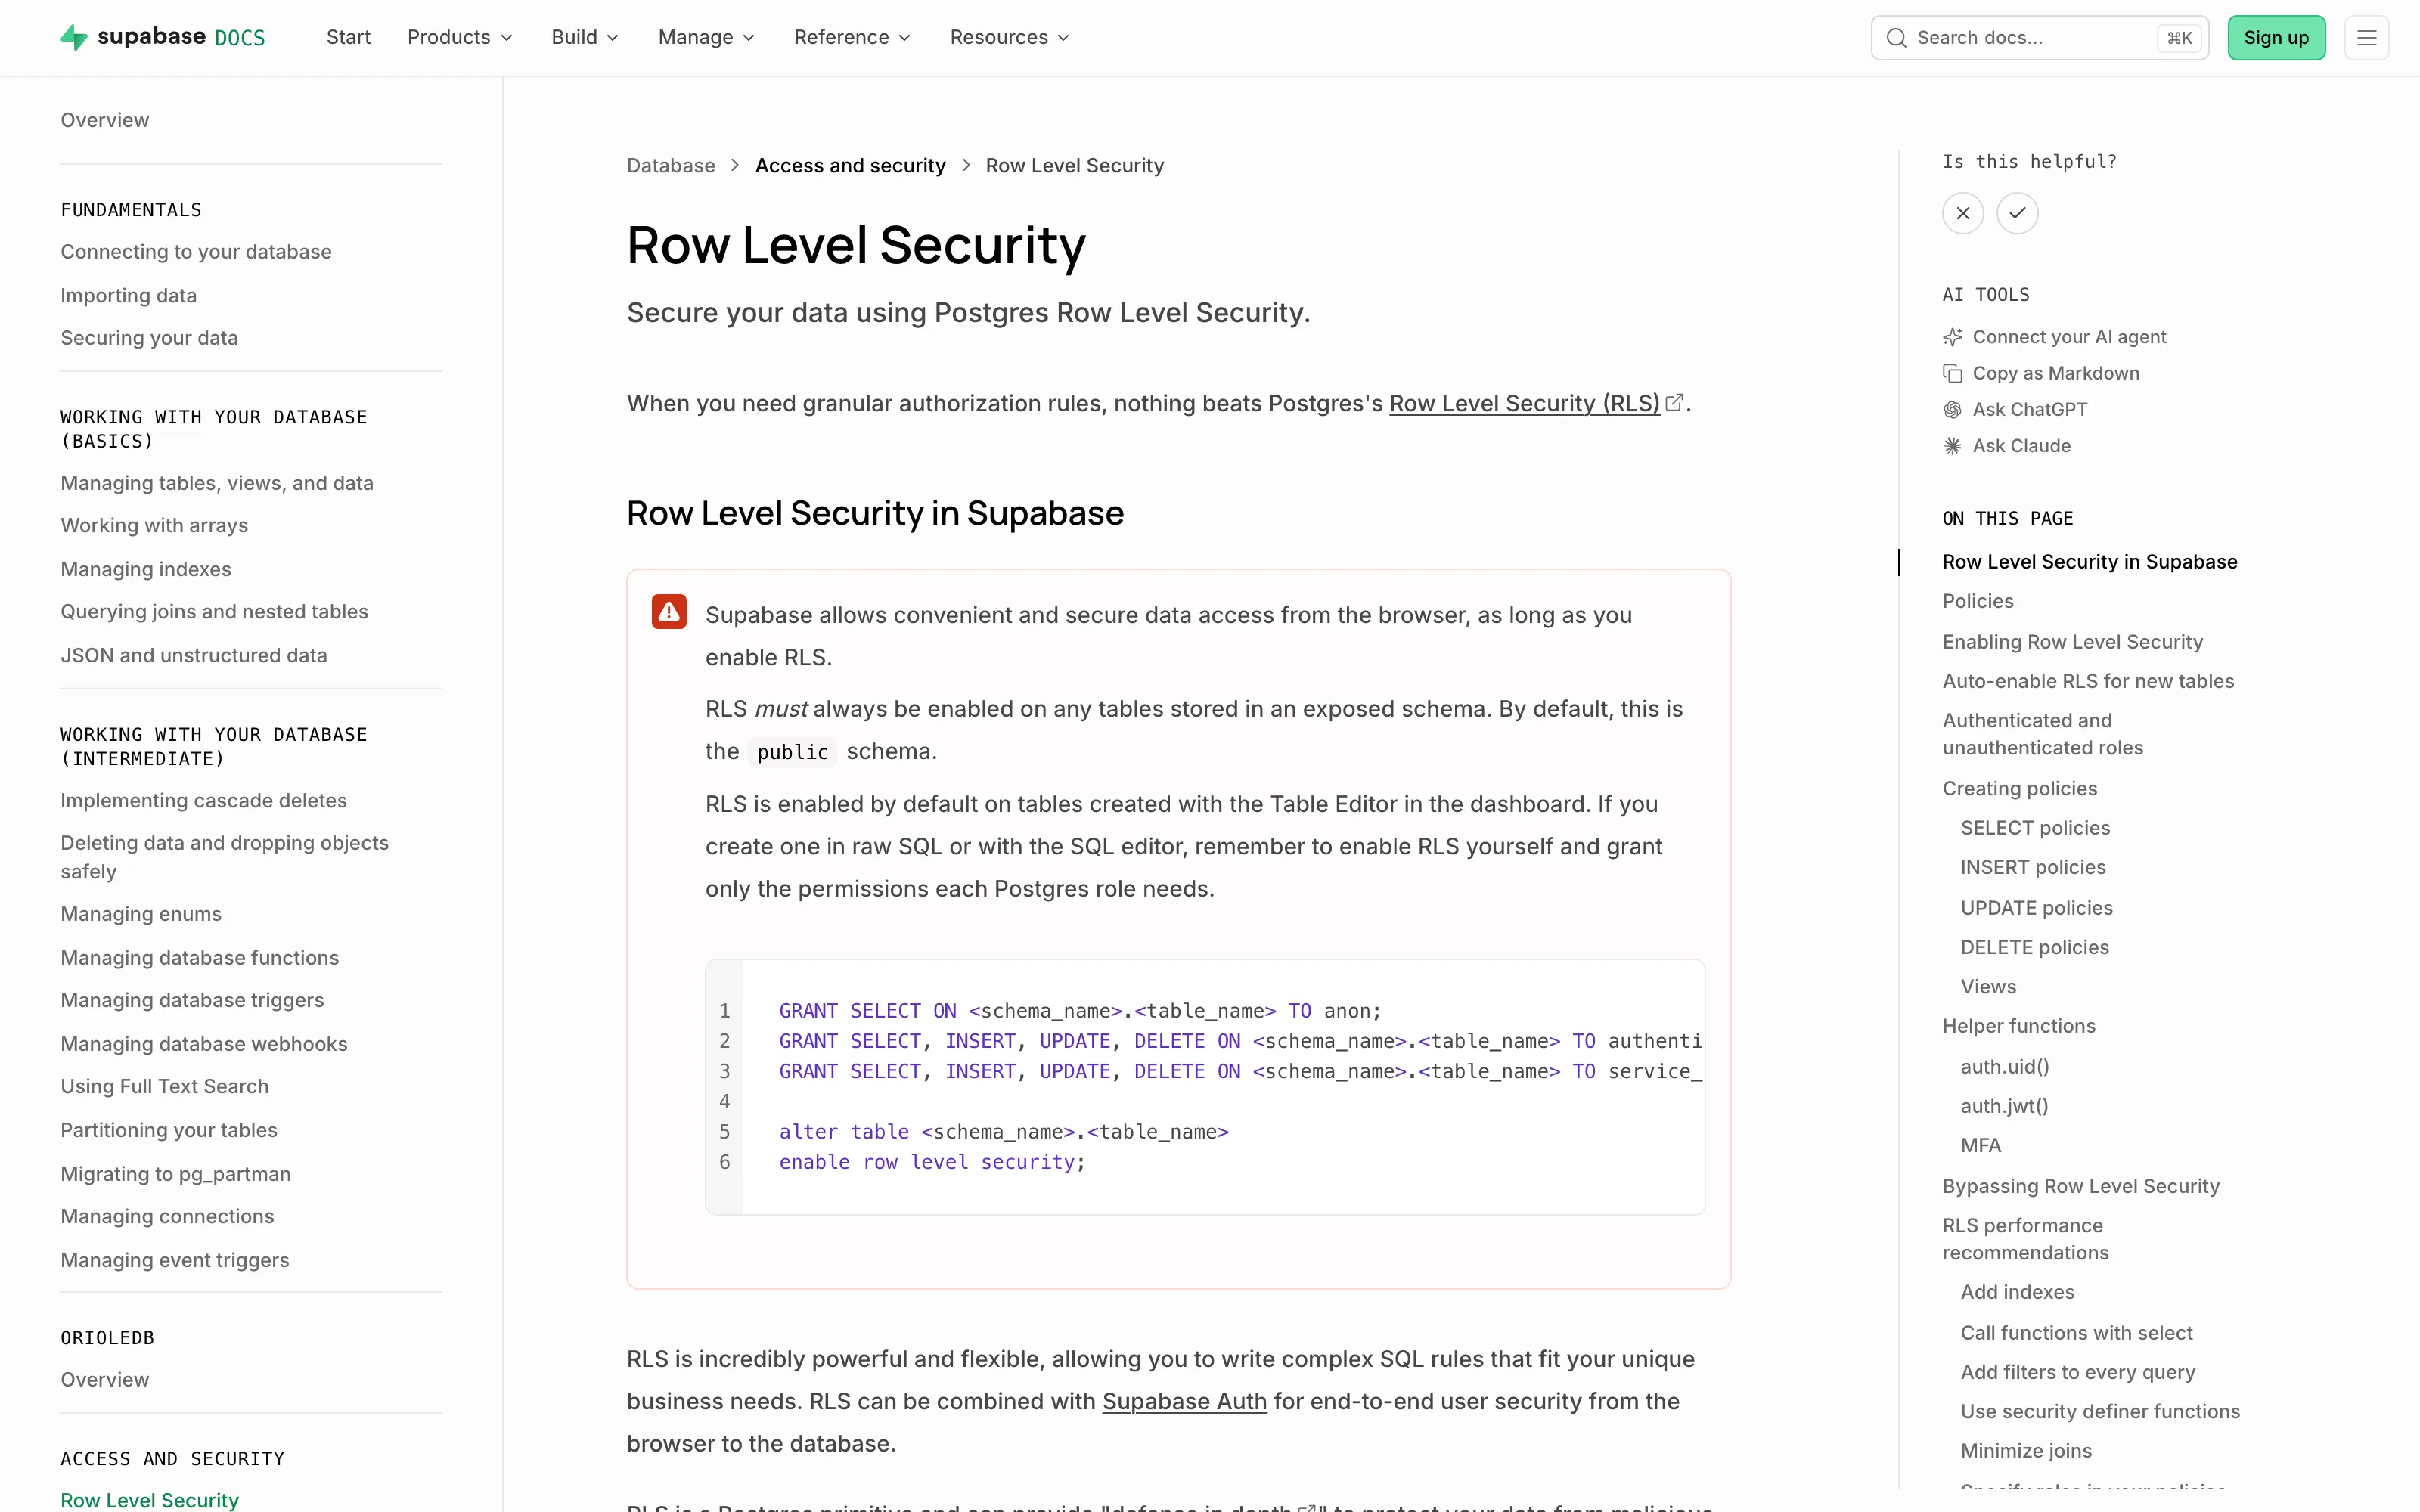 Supabase's rule for internal tools: RLS must be enabled on every table in an exposed schema, with the SQL to do it
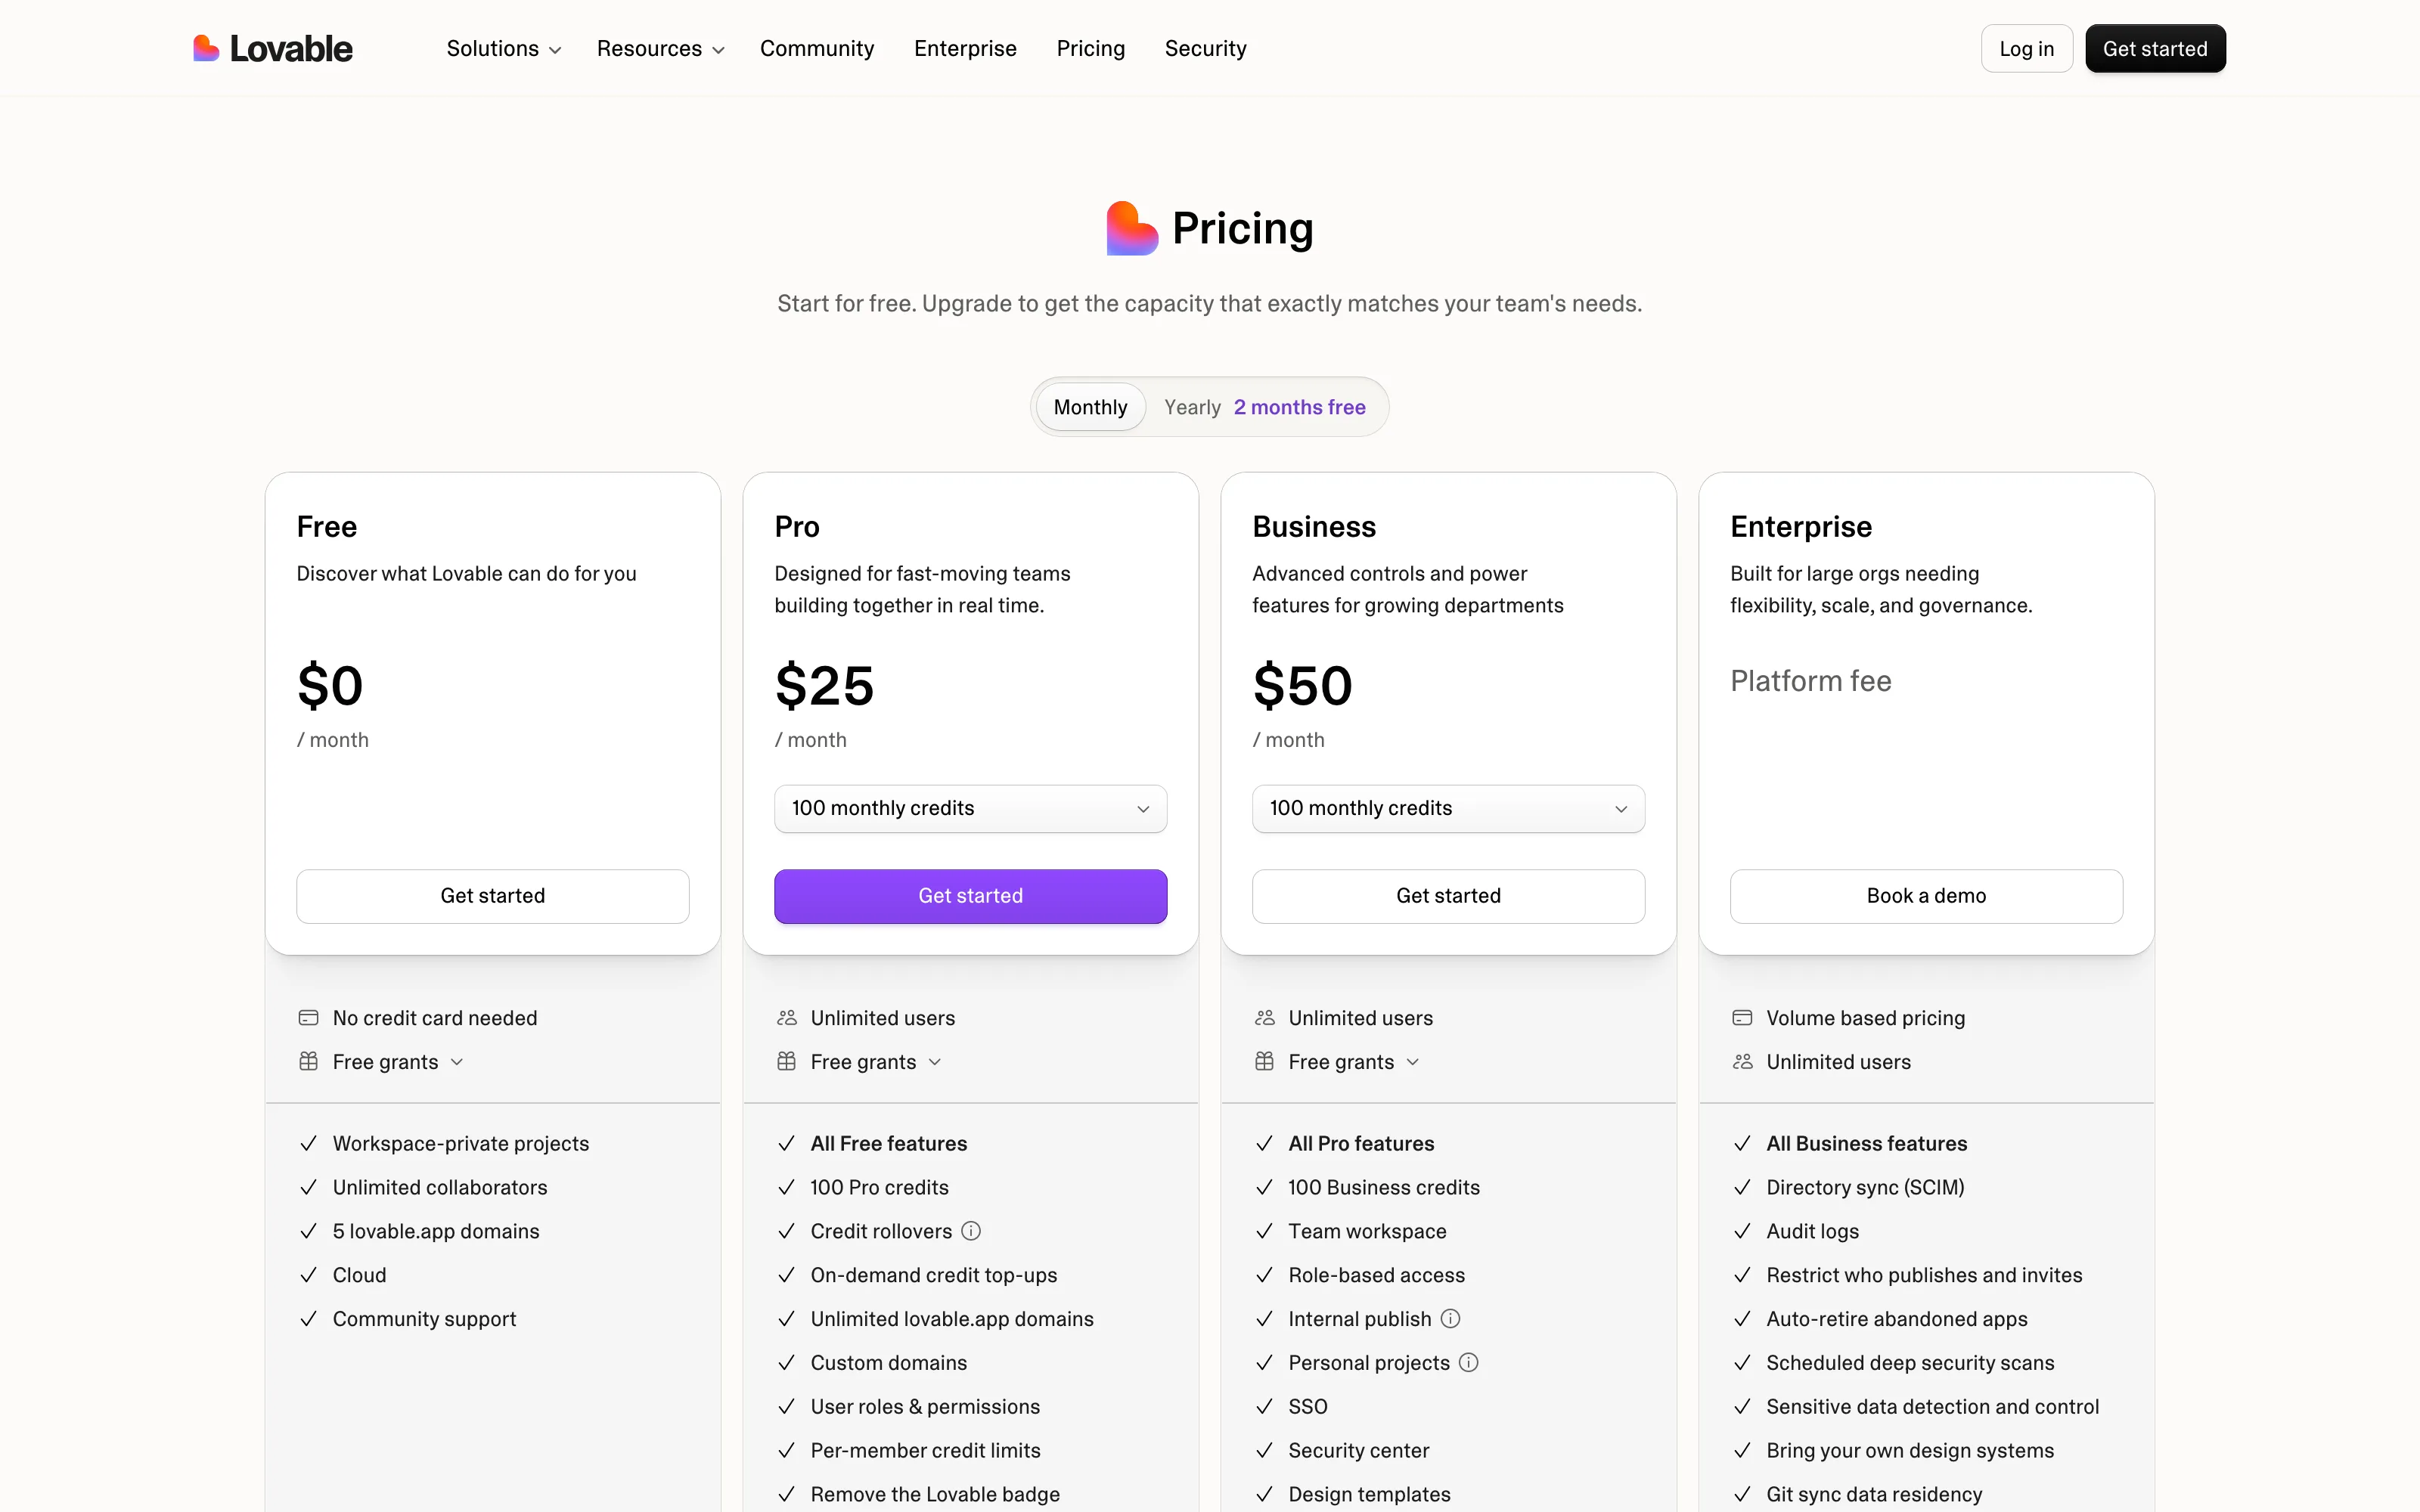 Lovable's plans: Free, Pro at $25/month and Business at $50/month, each paid tier carrying 100 monthly credits
تصفّح الموقع
الرئيسية
عن فيصل
قصتي
أعمالي
الذكاء الاصطناعي
Lovable
Notion
Webflow
Shopify
WordPress
حلول الذكاء الاصطناعي
الخدمات
استراتيجية الأعمال
تخطيط النمو
الأدوات
المدوّنة
ما أستمع إليه
أدواتي
تواصل
طلب عرض سعر
الخصوصية
شروط الاستخدام